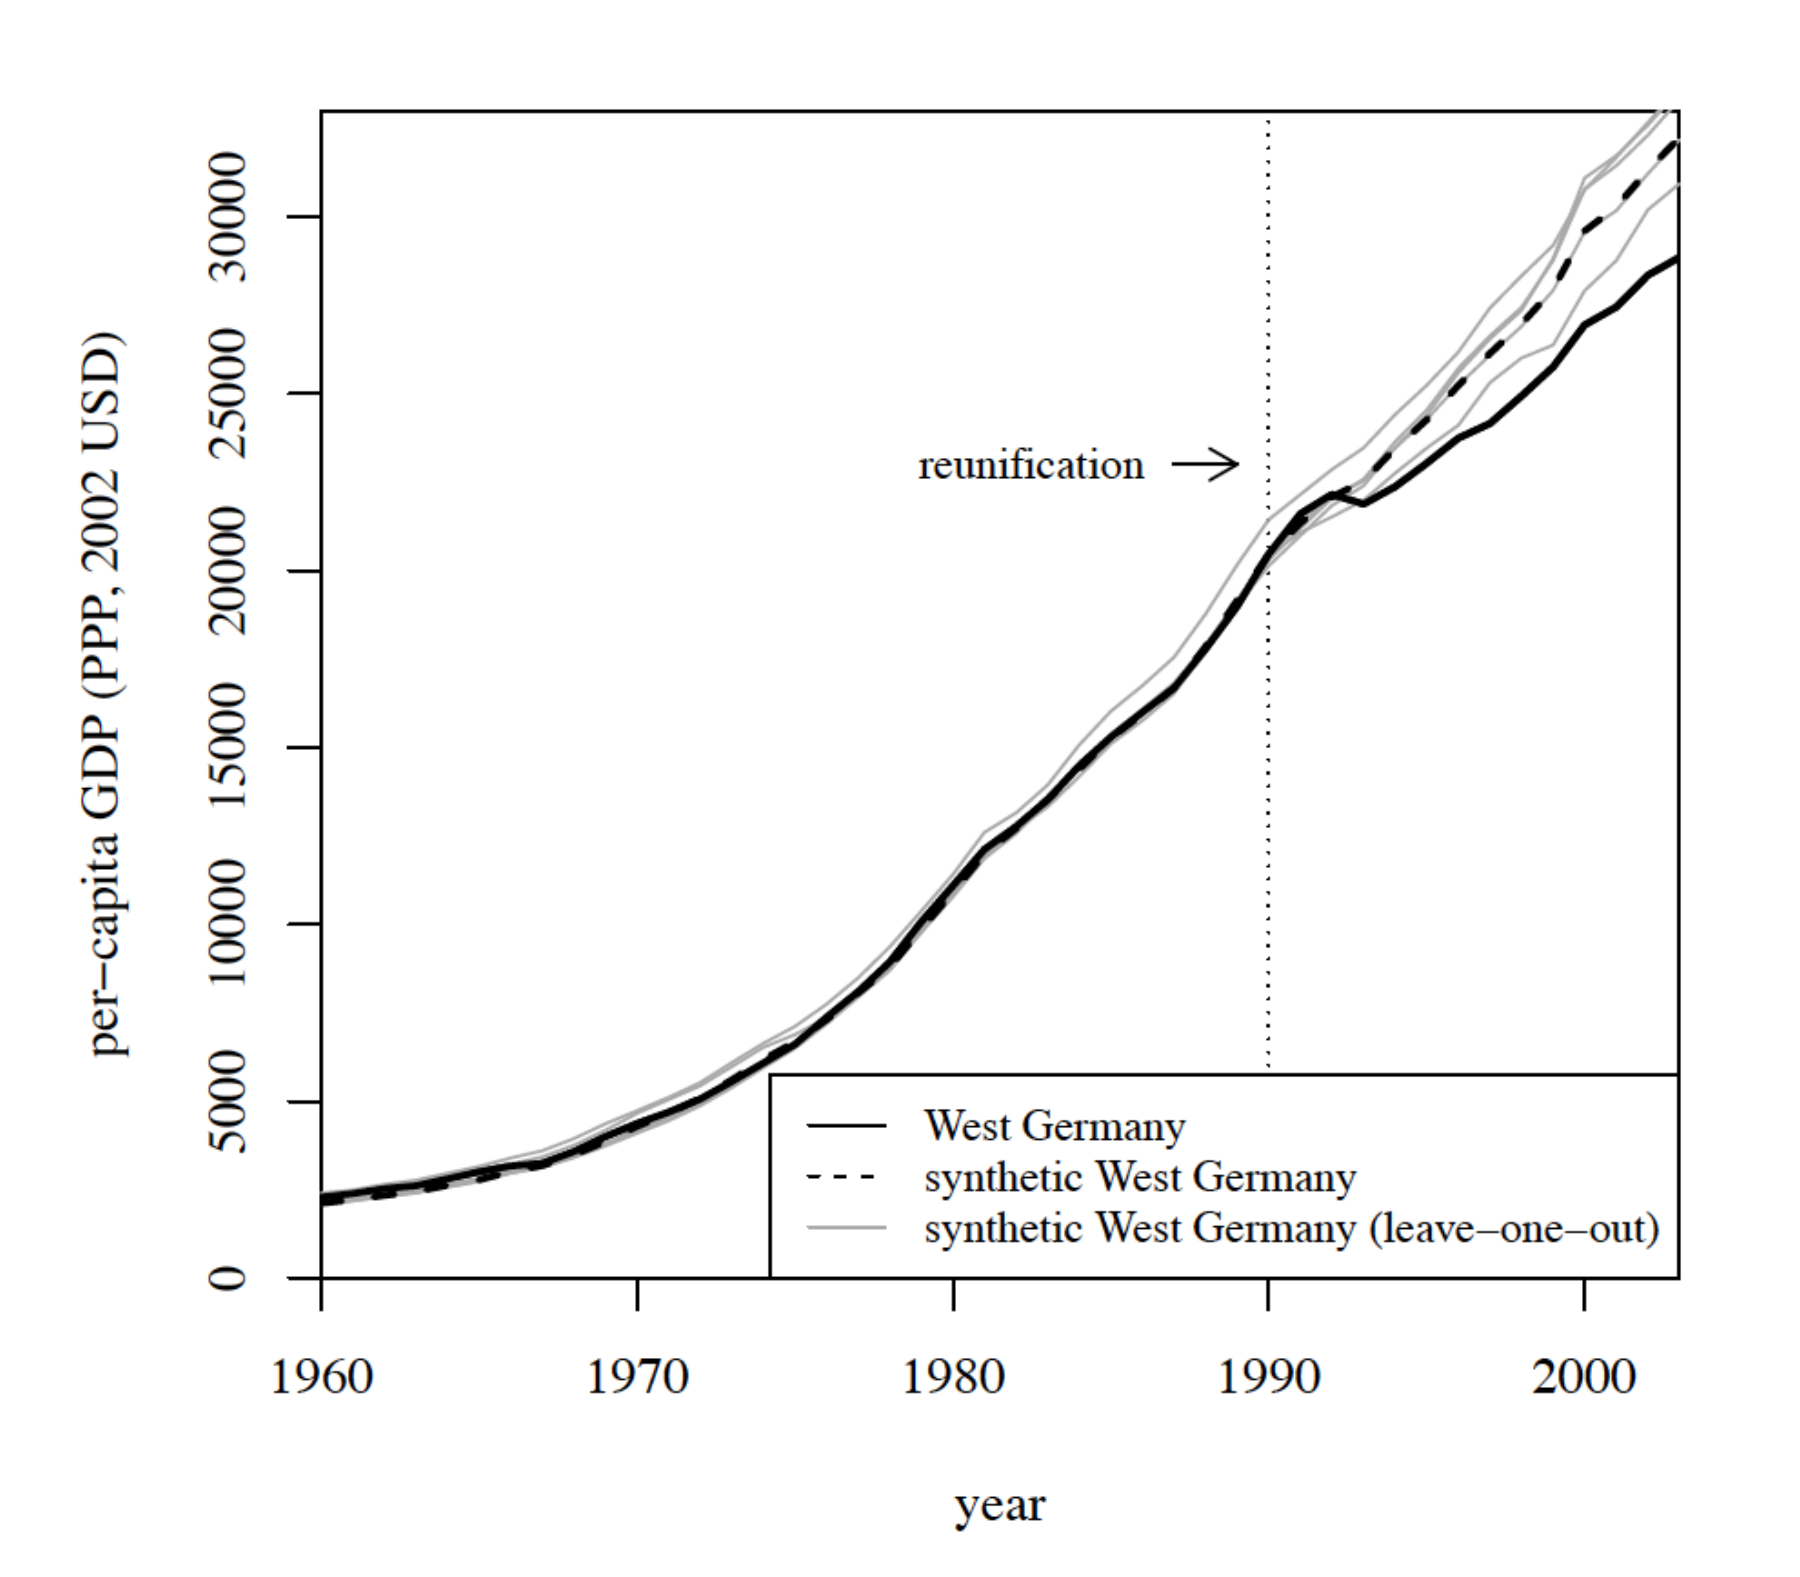
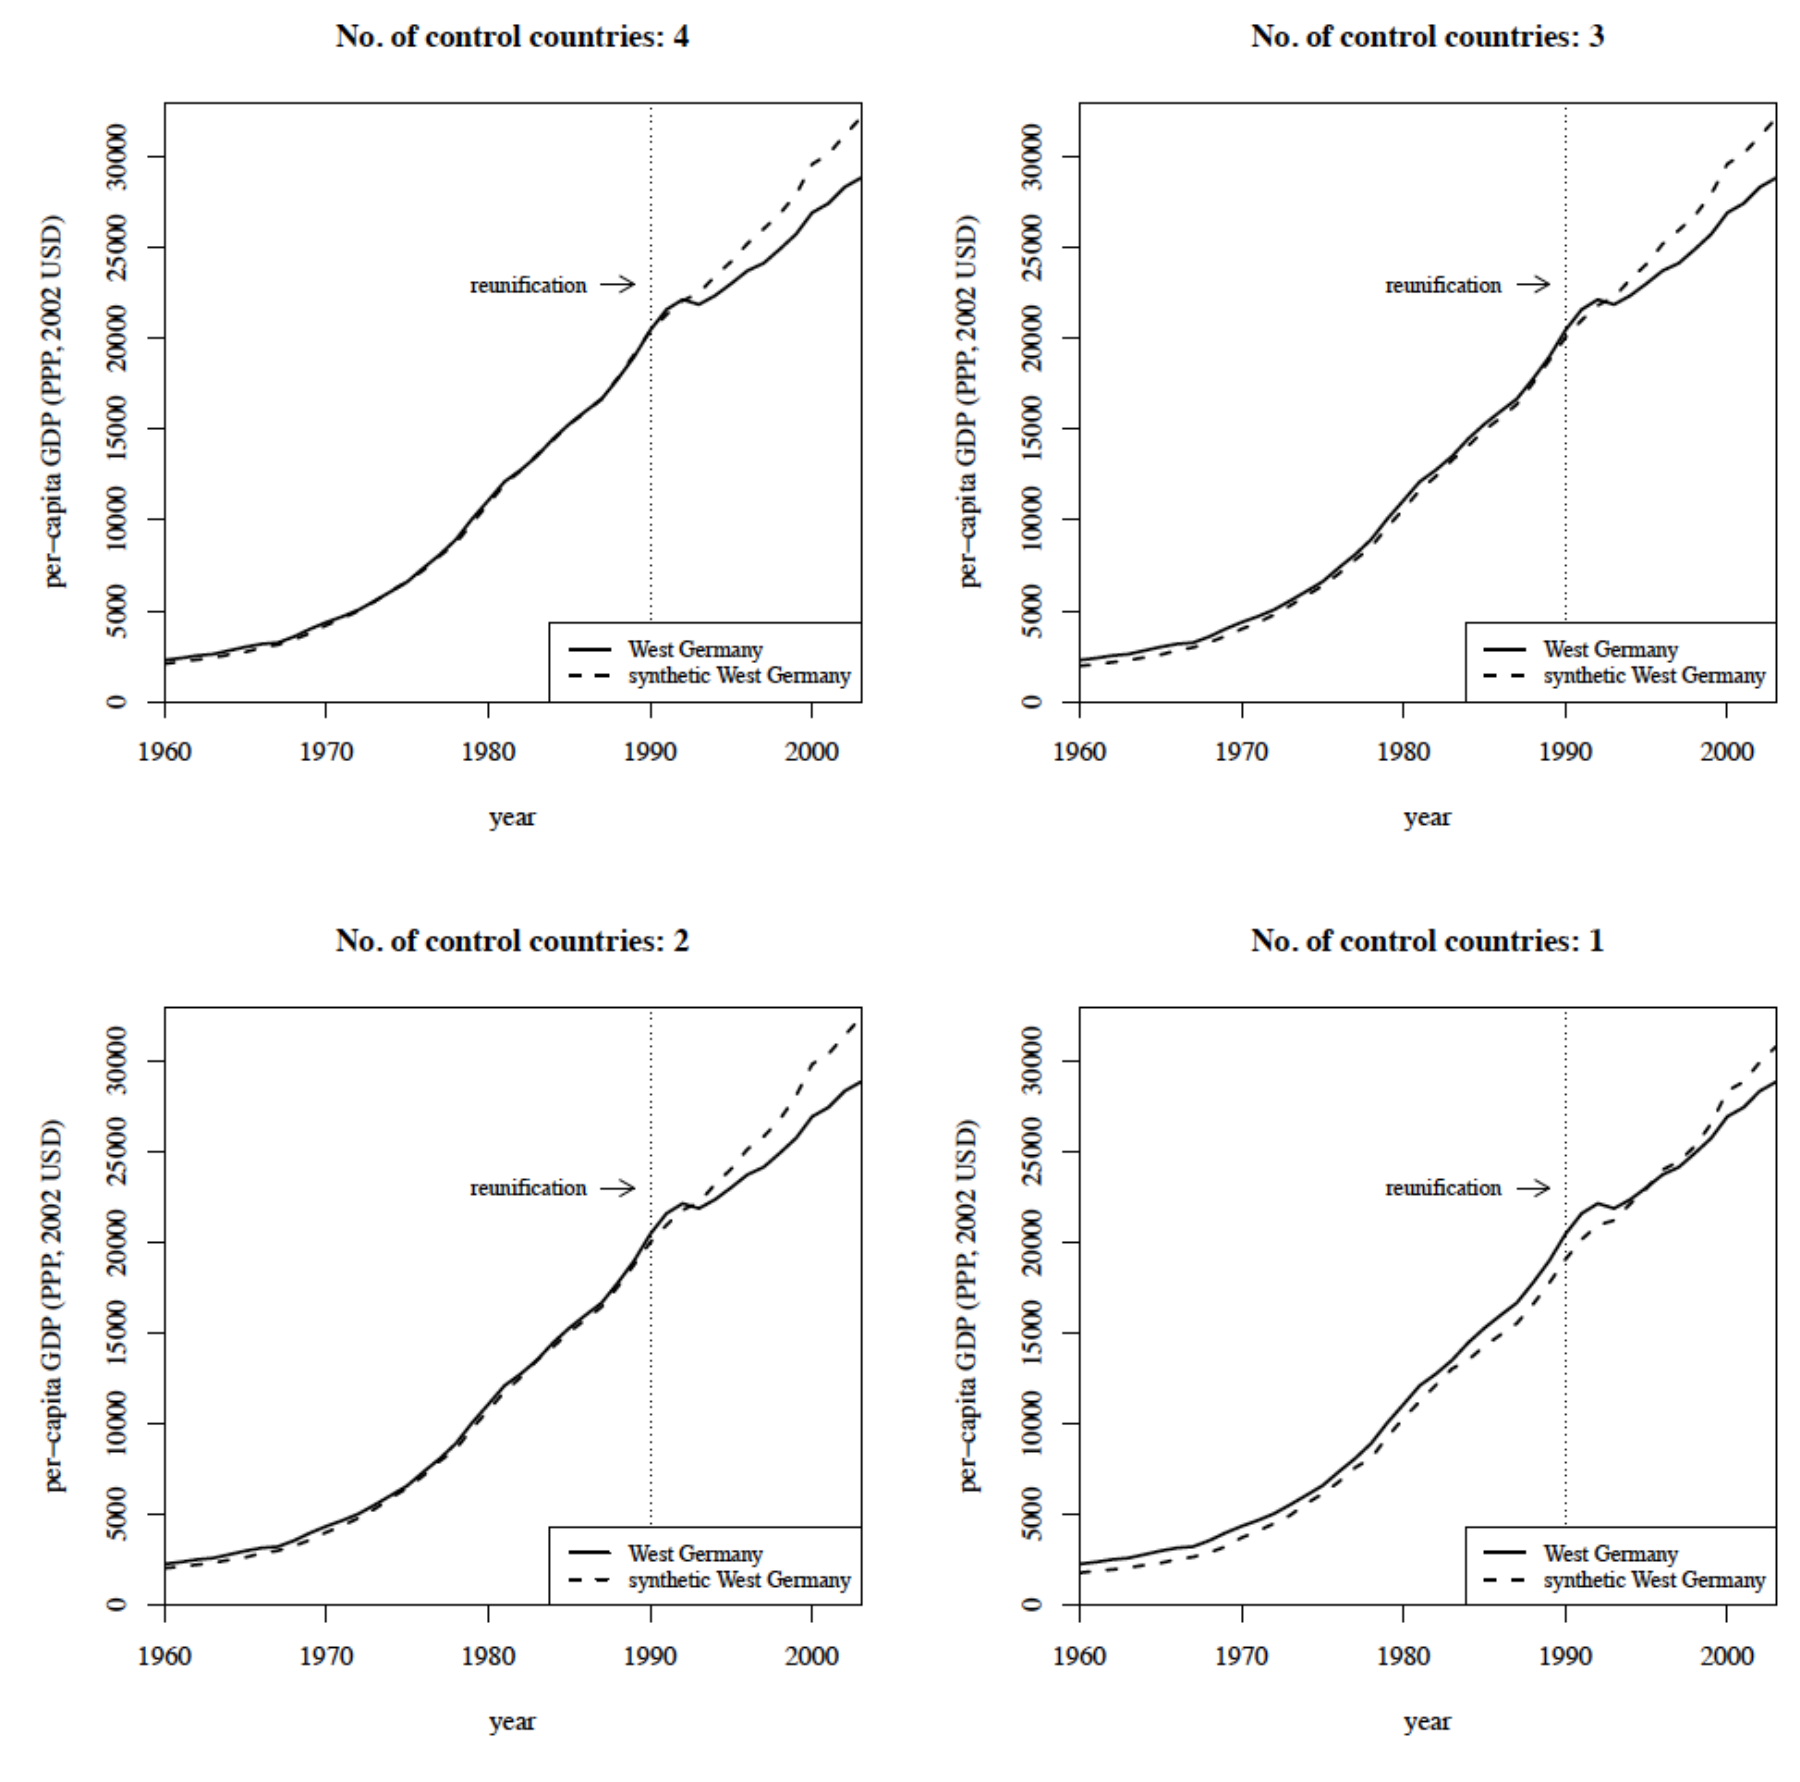
Synthetic Controls
PP5001 · Week 11 · Martinmas 2026
Professor David A. Jaeger
Choosing a Comparison Group
One of the fundamental issues with difference-in-differences is choosing the right control group.
Synthetic control uses pre-treatment data to choose weights for untreated units so that their weighted average resembles the treated unit.
The resulting synthetic control supplies an estimated counterfactual path after treatment.
The Counterfactual Problem
For treated unit 1, the effect at time t is
\tau_{1t}=Y_{1t}^{1}-Y_{1t}^{0}.
After treatment begins, we observe Y_{1t}=Y_{1t}^{1}.
We need Y_{1t}^{0}: the outcome that would have occurred without treatment.
From Difference-in-Differences
A simple DiD comparison is
\widehat\tau^{\mathrm{DiD}}=
\left(Y_{1,\mathrm{post}}-Y_{1,\mathrm{pre}}\right)
-\left(\bar Y_{C,\mathrm{post}}-\bar Y_{C,\mathrm{pre}}\right).
The choice of controls determines \bar Y_{C,t}.
We could use one comparison unit, a simple average, a population-weighted average, or weights selected using pre-treatment data.
The Basic Idea
Donor units remain untreated, so Y_{jt}=Y_{jt}^{0} for j=2,\ldots,J+1.
Construct the counterfactual:
\widehat Y_{1t}^{0}=\sum_{j=2}^{J+1}w_jY_{jt}.
Then estimate the effect:
\widehat\tau_{1t}=Y_{1t}-\widehat Y_{1t}^{0}.
How do we choose the donor weights w_j?
Setup
- One treated unit, indexed by 1.
- J untreated units in the donor pool.
- A balanced panel observed for T periods.
- T_0 pre-treatment periods, with treatment beginning in period T_0+1.
- T_1=T-T_0 post-treatment periods.
Donor Weights
The standard method imposes
w_j\ge0\quad\text{for every donor }j,
and
\sum_{j=2}^{J+1}w_j=1.
The synthetic unit is a weighted average of observed donor units.
Some donors can receive zero weight.
Predictors and Pre-Treatment Outcomes
Let X_{hj} be predictor h for unit j, for h=1,\ldots,K.
Predictors can include:
- Observable characteristics measured before treatment.
- Selected pre-treatment outcomes.
- Pre-treatment averages of outcomes.
The synthetic value of predictor h is \sum_{j=2}^{J+1}w_jX_{hj}.
Choosing the Donor Weights
Choose w_2,\ldots,w_{J+1} to minimize
\sum_{h=1}^{K}v_h
\left(X_{h1}-\sum_{j=2}^{J+1}w_jX_{hj}\right)^2,
subject to w_j\ge0 and \sum_{j=2}^{J+1}w_j=1.
The expression in parentheses is the treated–synthetic difference for predictor h.
v_h determines how much that predictor contributes to the criterion.
Two Different Sets of Weights
Donor weights w_j: how much each state or country contributes to the synthetic unit.
Predictor weights v_h: how much each predictor matters when choosing that combination.
Large v_h places more emphasis on matching predictor h.
The choice of predictor weights can change the donor weights.
Choosing Predictor Weights
One option is v_h=1/\sigma_h^2, where \sigma_h^2 is the variance of predictor h across units.
Another is to choose predictor weights that produce good pre-treatment outcome predictions.
We can assess prediction using a training period and a later validation period, both before treatment.
How Many Pre-Treatment Outcomes?
- Too few periods may miss important differences in outcome paths.
- Matching many noisy outcomes can fit transitory fluctuations.
- Using every lag as a separate predictor can make additional covariates redundant in common fitting procedures.
- Compare reasonable predictor sets and pre-treatment windows.
Geometry of Synthetic Control
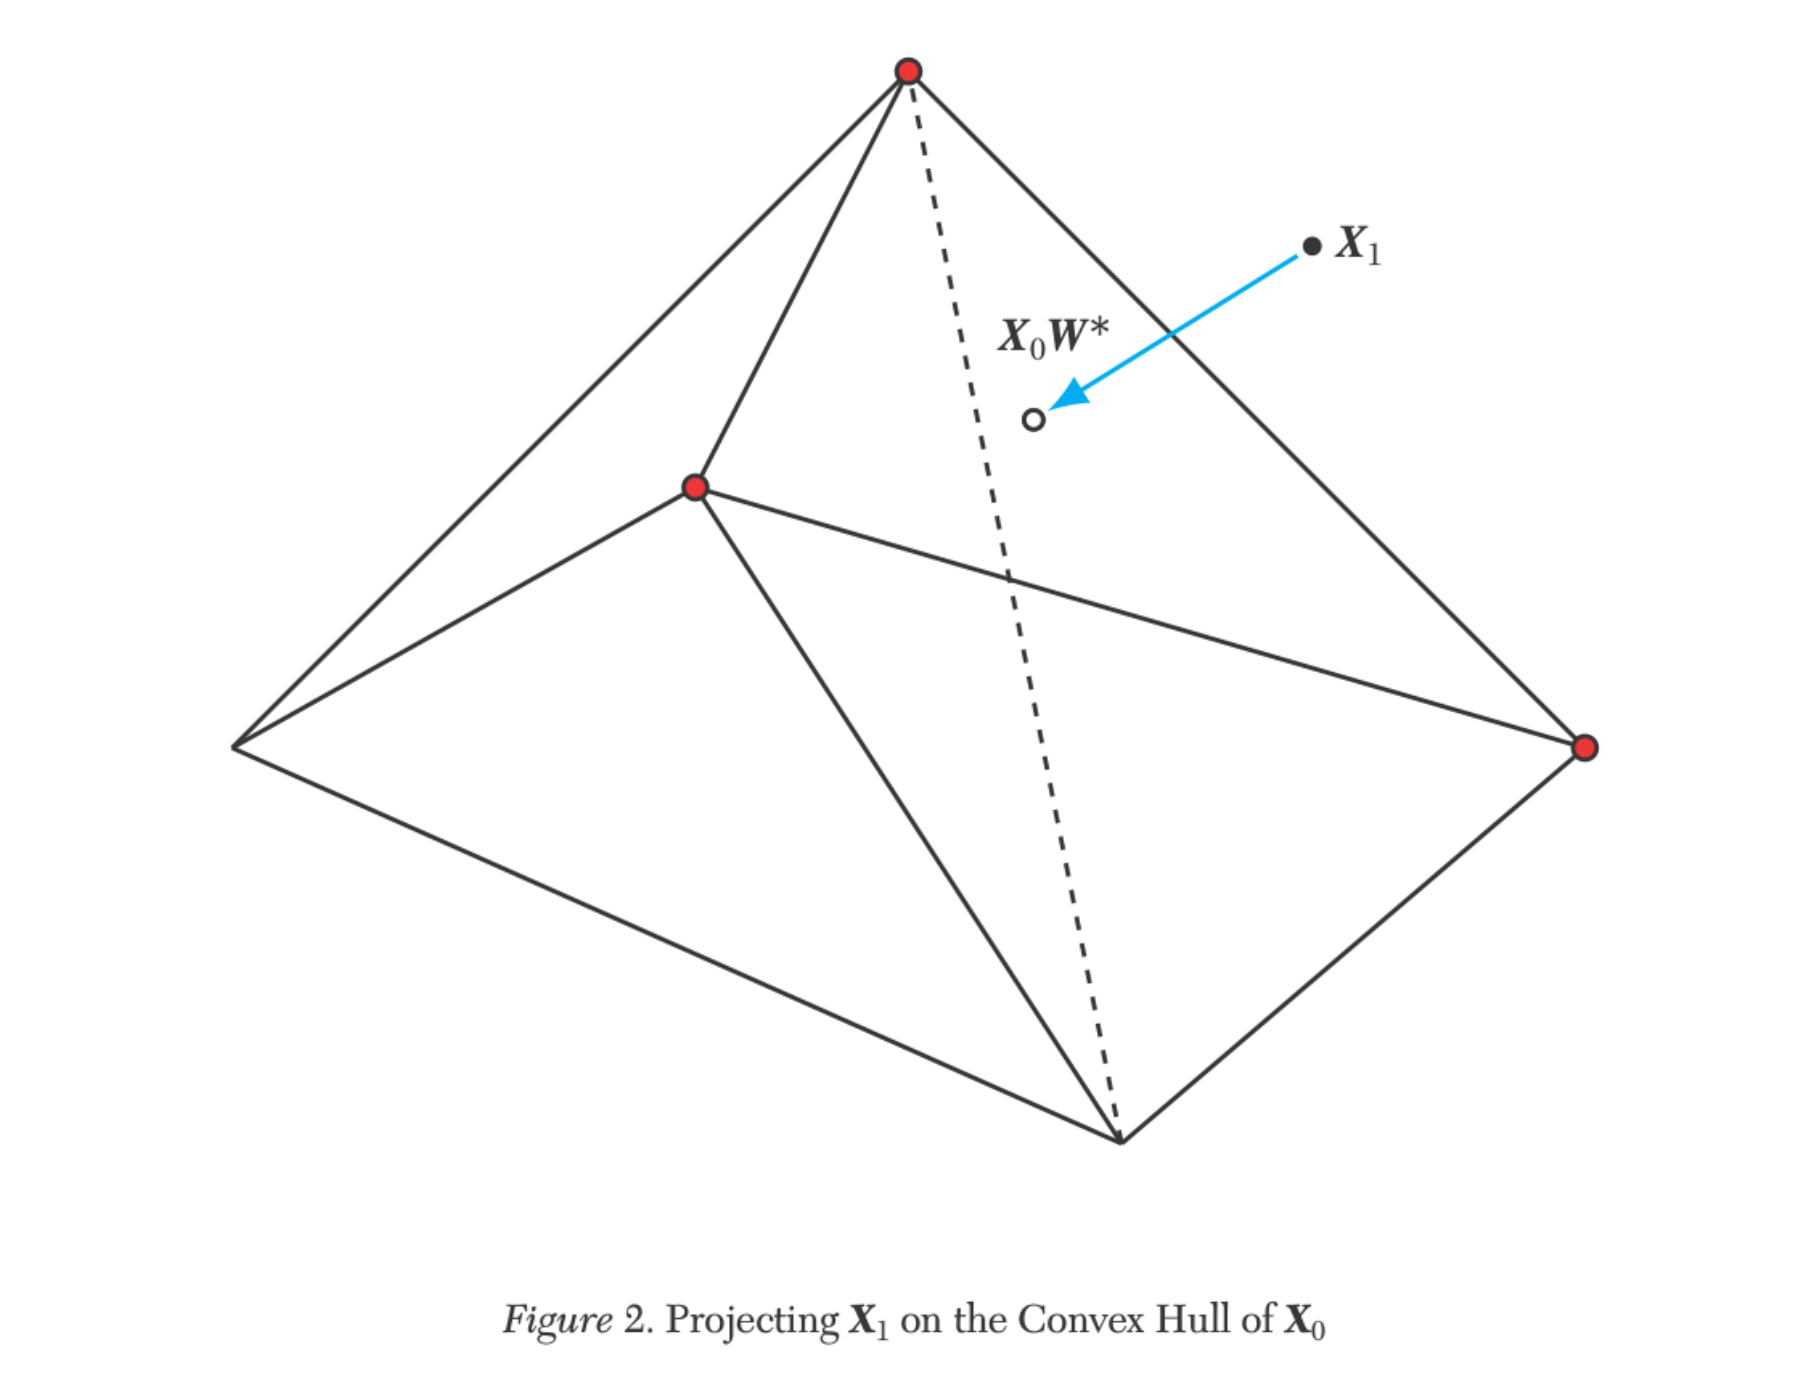
![]()
Abadie (2021), illustration from the original lecture slides.
For discussion: What combinations of donor units are available under nonnegative weights that sum to one?
Synthetic Control and OLS Weights
The regression comparison used in the German application has implied donor weights that sum to one because the regression includes an intercept.
Those weights can be negative.
Those weights allow extrapolation beyond the donor pool.
Synthetic control restricts the fitted comparison to weighted averages of the donors.
A close fit should be assessed alongside the weights that produce it.
From Fit to a Causal Interpretation
The donor combination must continue to approximate the treated unit’s untreated outcome after the intervention.
That requires attention to:
- Stable relationships between treated and donor outcomes.
- No anticipation during the fitting period.
- Untreated donors and limited spillovers.
- Other shocks unique to the treated unit at the intervention date.
The Gap
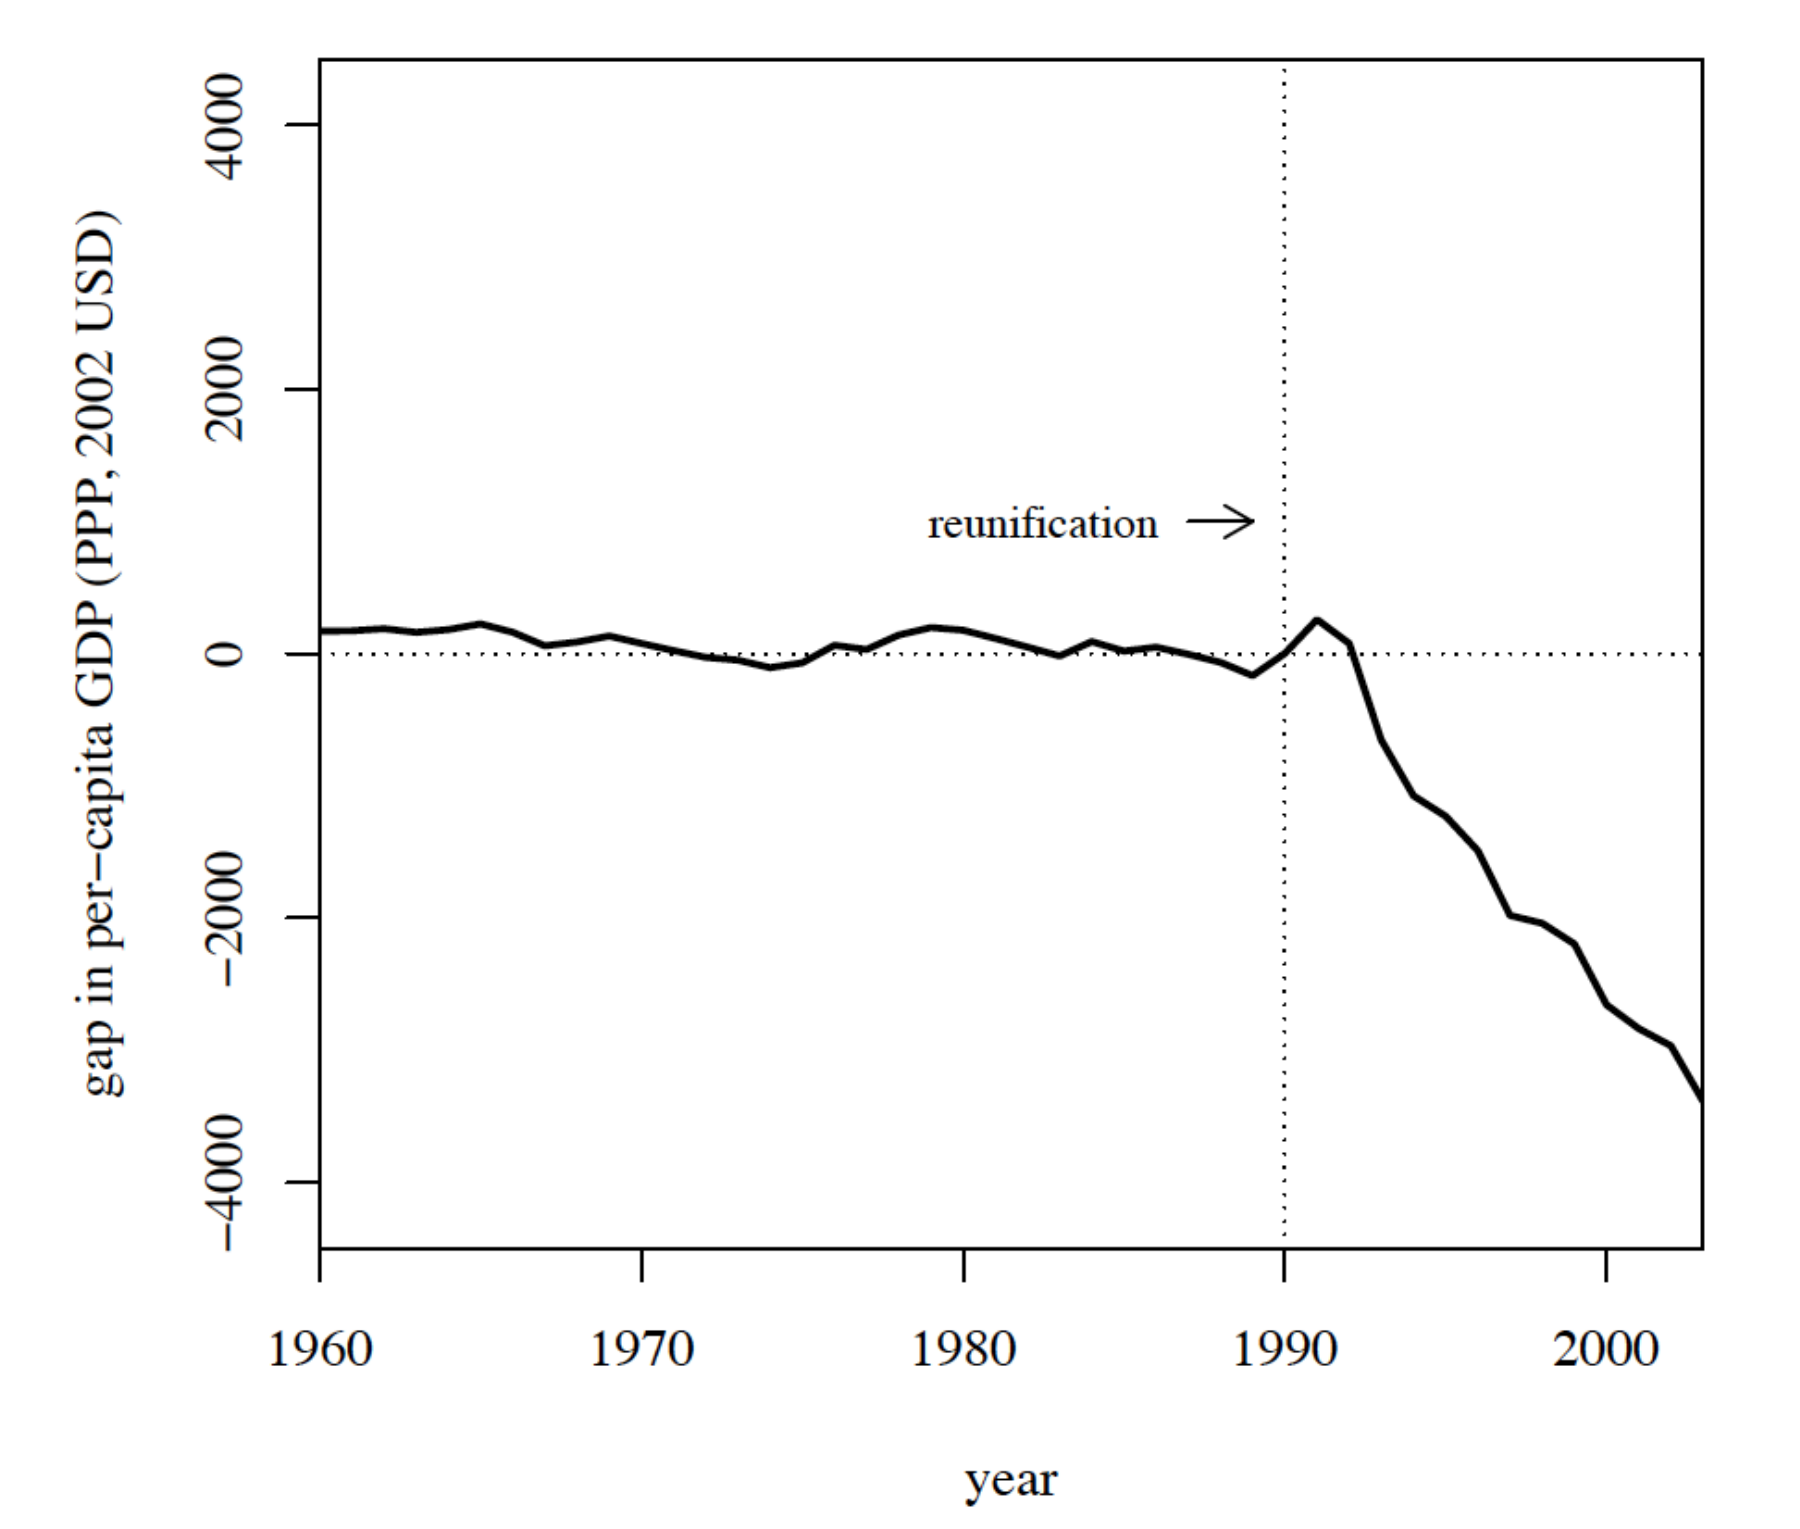
Using the fitted donor weights w_j^*, define
g_{1t}=Y_{1t}-\sum_{j=2}^{J+1}w_j^*Y_{jt}.
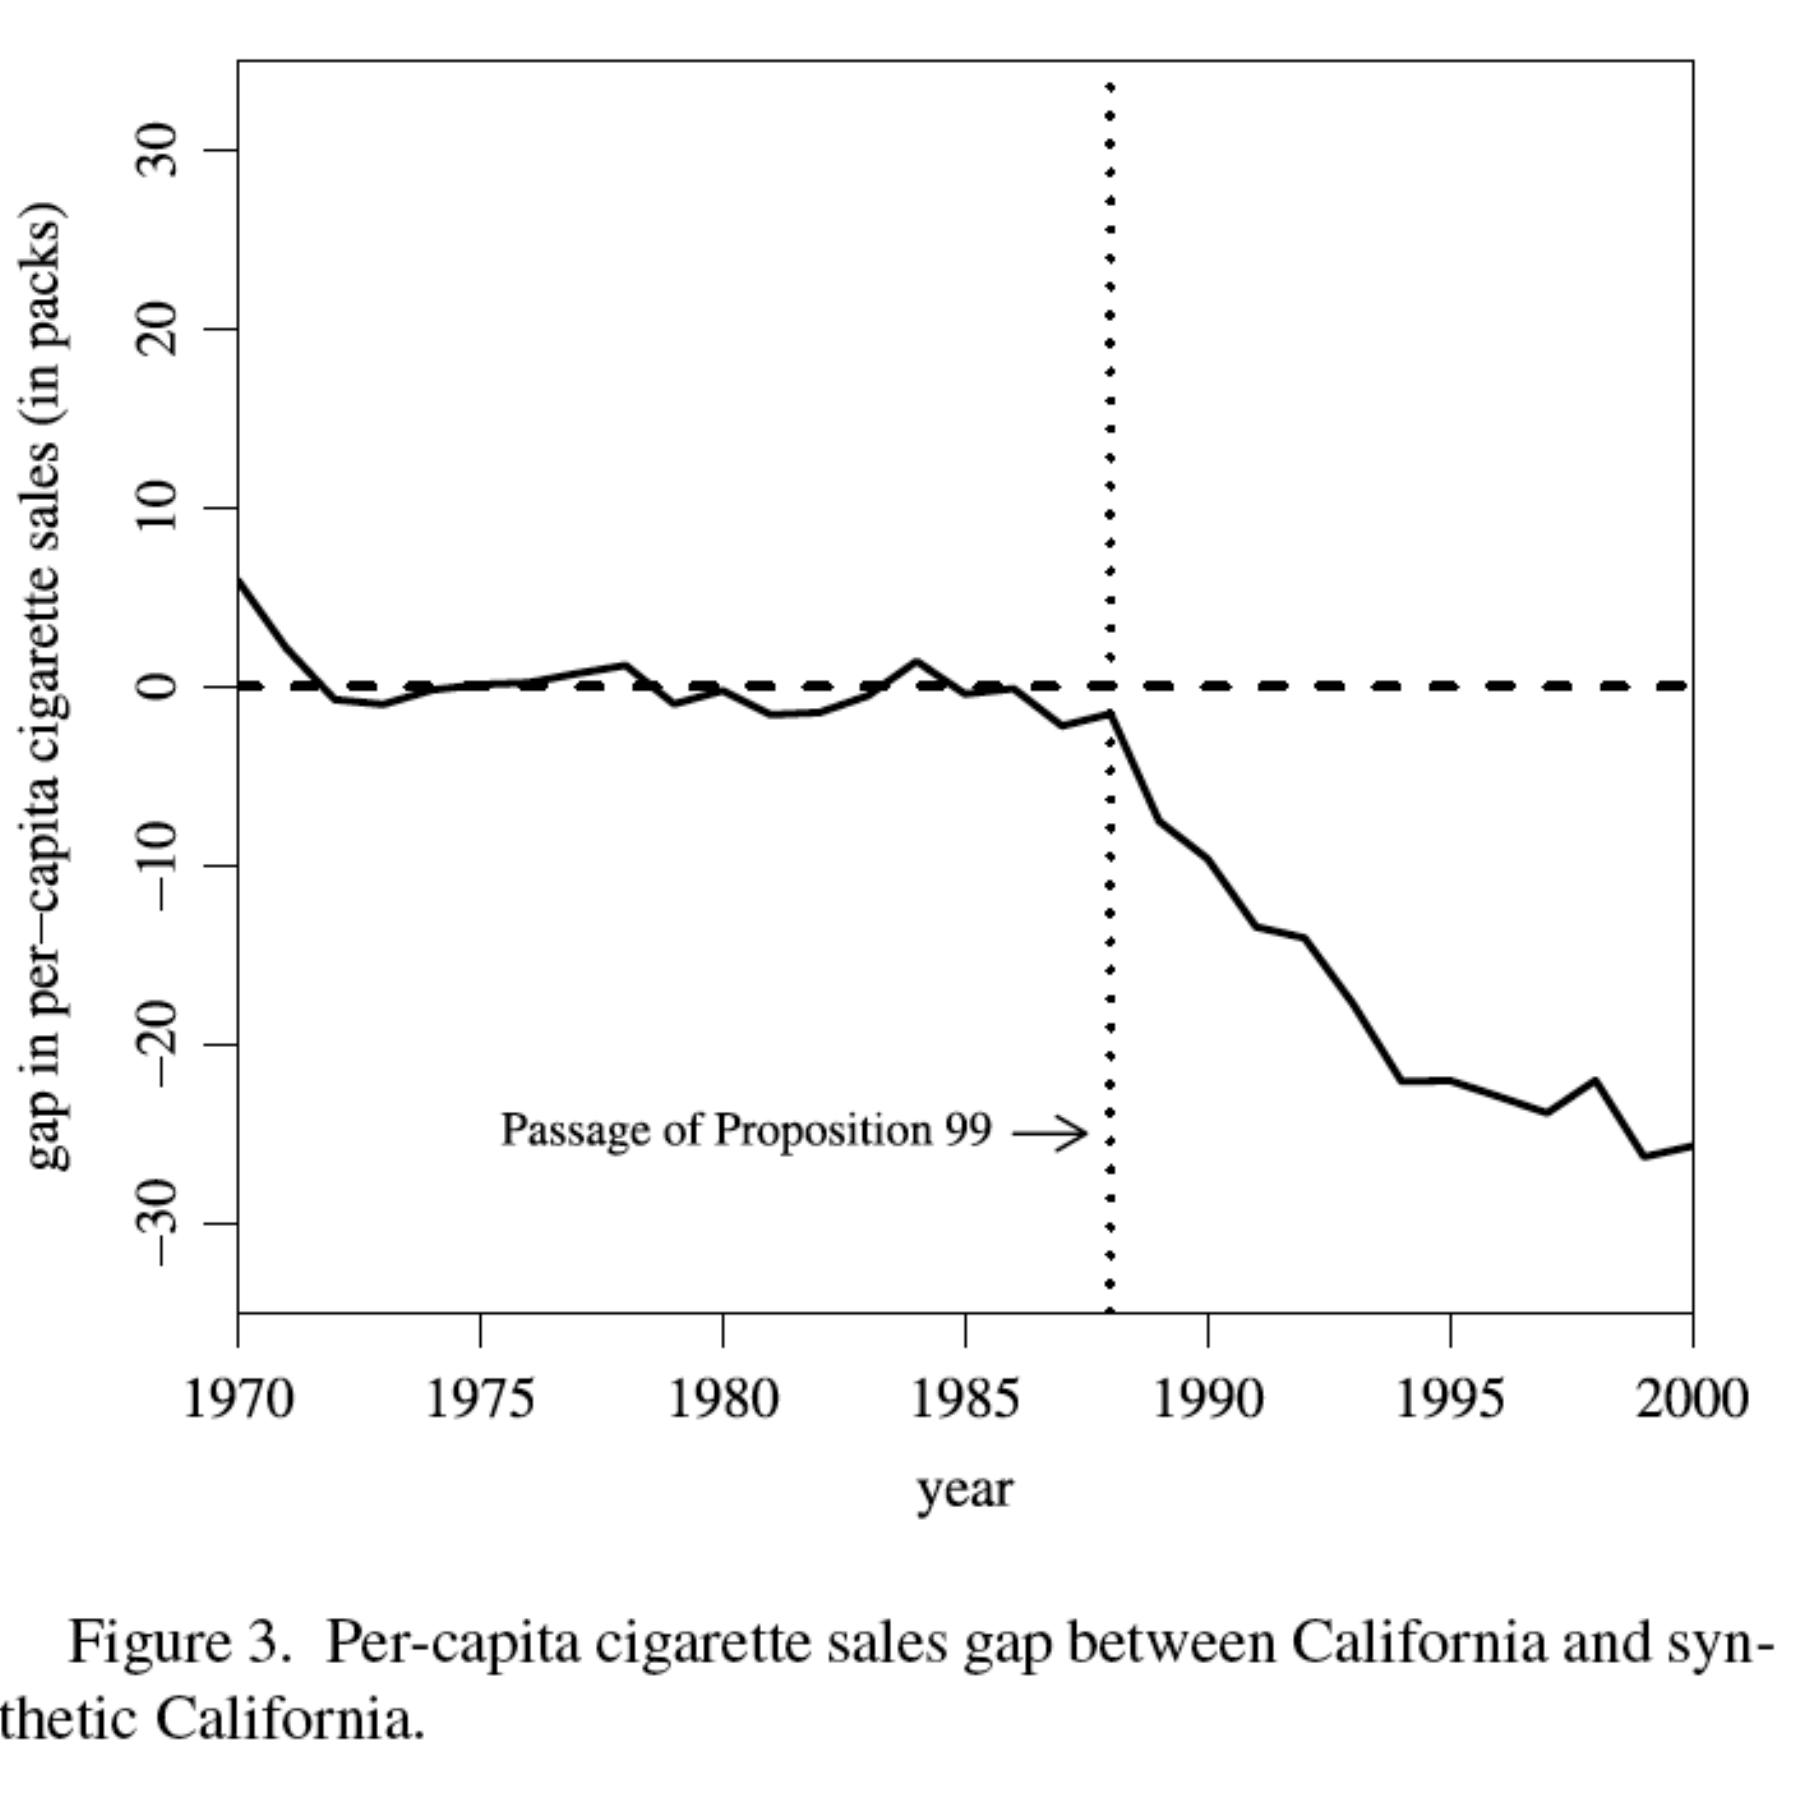
Before treatment, the gap measures fit.
After treatment,
g_{1t}=\widehat\tau_{1t}.
Interpret the gap in the units of the outcome.
Why Inference Is Difficult
These applications have:
- One treated state or country.
- One intervention date.
- Outcomes related across years.
- A particular set of potential comparison units.
We need to assess how unusual the treated unit’s gap is.
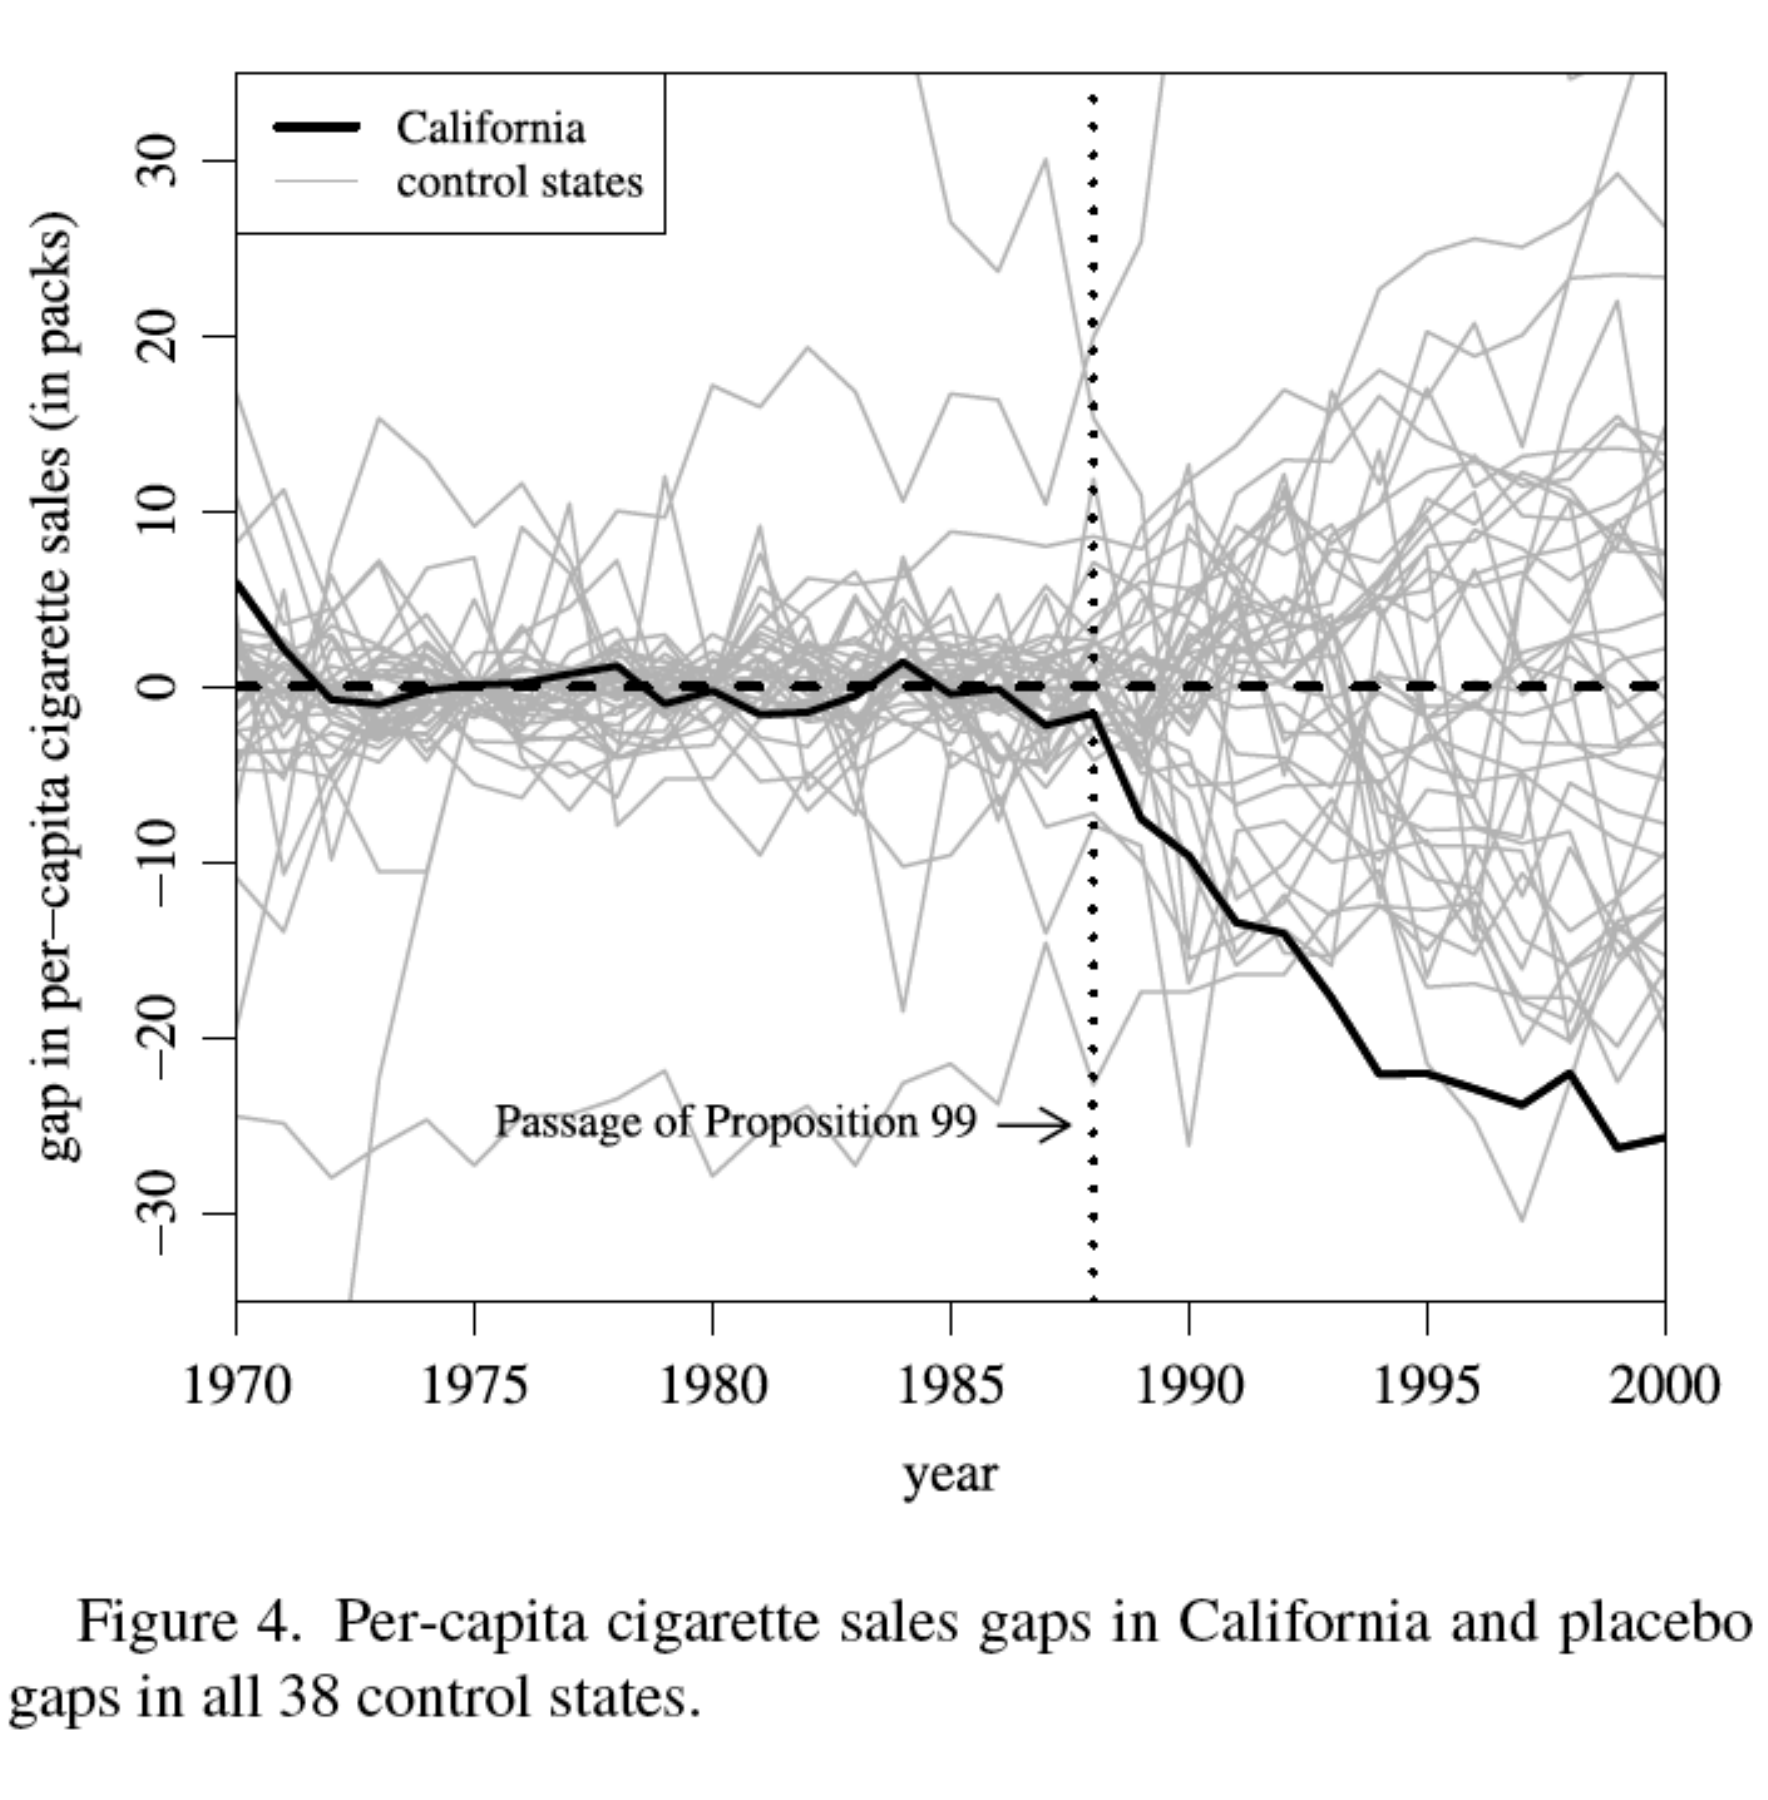
In-Space Placebos
- Treat a donor unit as if it received the intervention at the same date.
- Fit a synthetic control for that unit from the other untreated donors.
- Calculate its pre- and post-treatment gaps.
- Repeat for the remaining donors.
- Compare the actual treated gap with the placebo gaps.
Comparing Pre- and Post-Treatment Fit
The mean squared prediction error (MSPE) is
\operatorname{MSPE}_{i}^{\mathrm{pre}}
=\frac{1}{T_0}\sum_{t=1}^{T_0}g_{it}^2,
and
\operatorname{MSPE}_{i}^{\mathrm{post}}
=\frac{1}{T_1}\sum_{t=T_0+1}^{T}g_{it}^2.
Squaring the gaps gives more weight to large discrepancies.
The Post/Pre MSPE Ratio
R_i=\frac{\operatorname{MSPE}_{i}^{\mathrm{post}}}
{\operatorname{MSPE}_{i}^{\mathrm{pre}}}.
A large ratio means prediction error is much larger after the intervention than before it.
Compare the treated unit’s ratio with the placebo ratios.
Also inspect the outcome and gap plots.
A Placebo Rank
Rank the treated unit among all J+1 units:
p=\frac{\text{number of units with }R_i\ge R_1}{J+1}.
The treated unit is included in both counts.
The smallest possible value is 1/(J+1).
With 19 donors, the smallest possible value is 1/20=0.05.
Pre-Treatment Fit and Placebo Comparisons
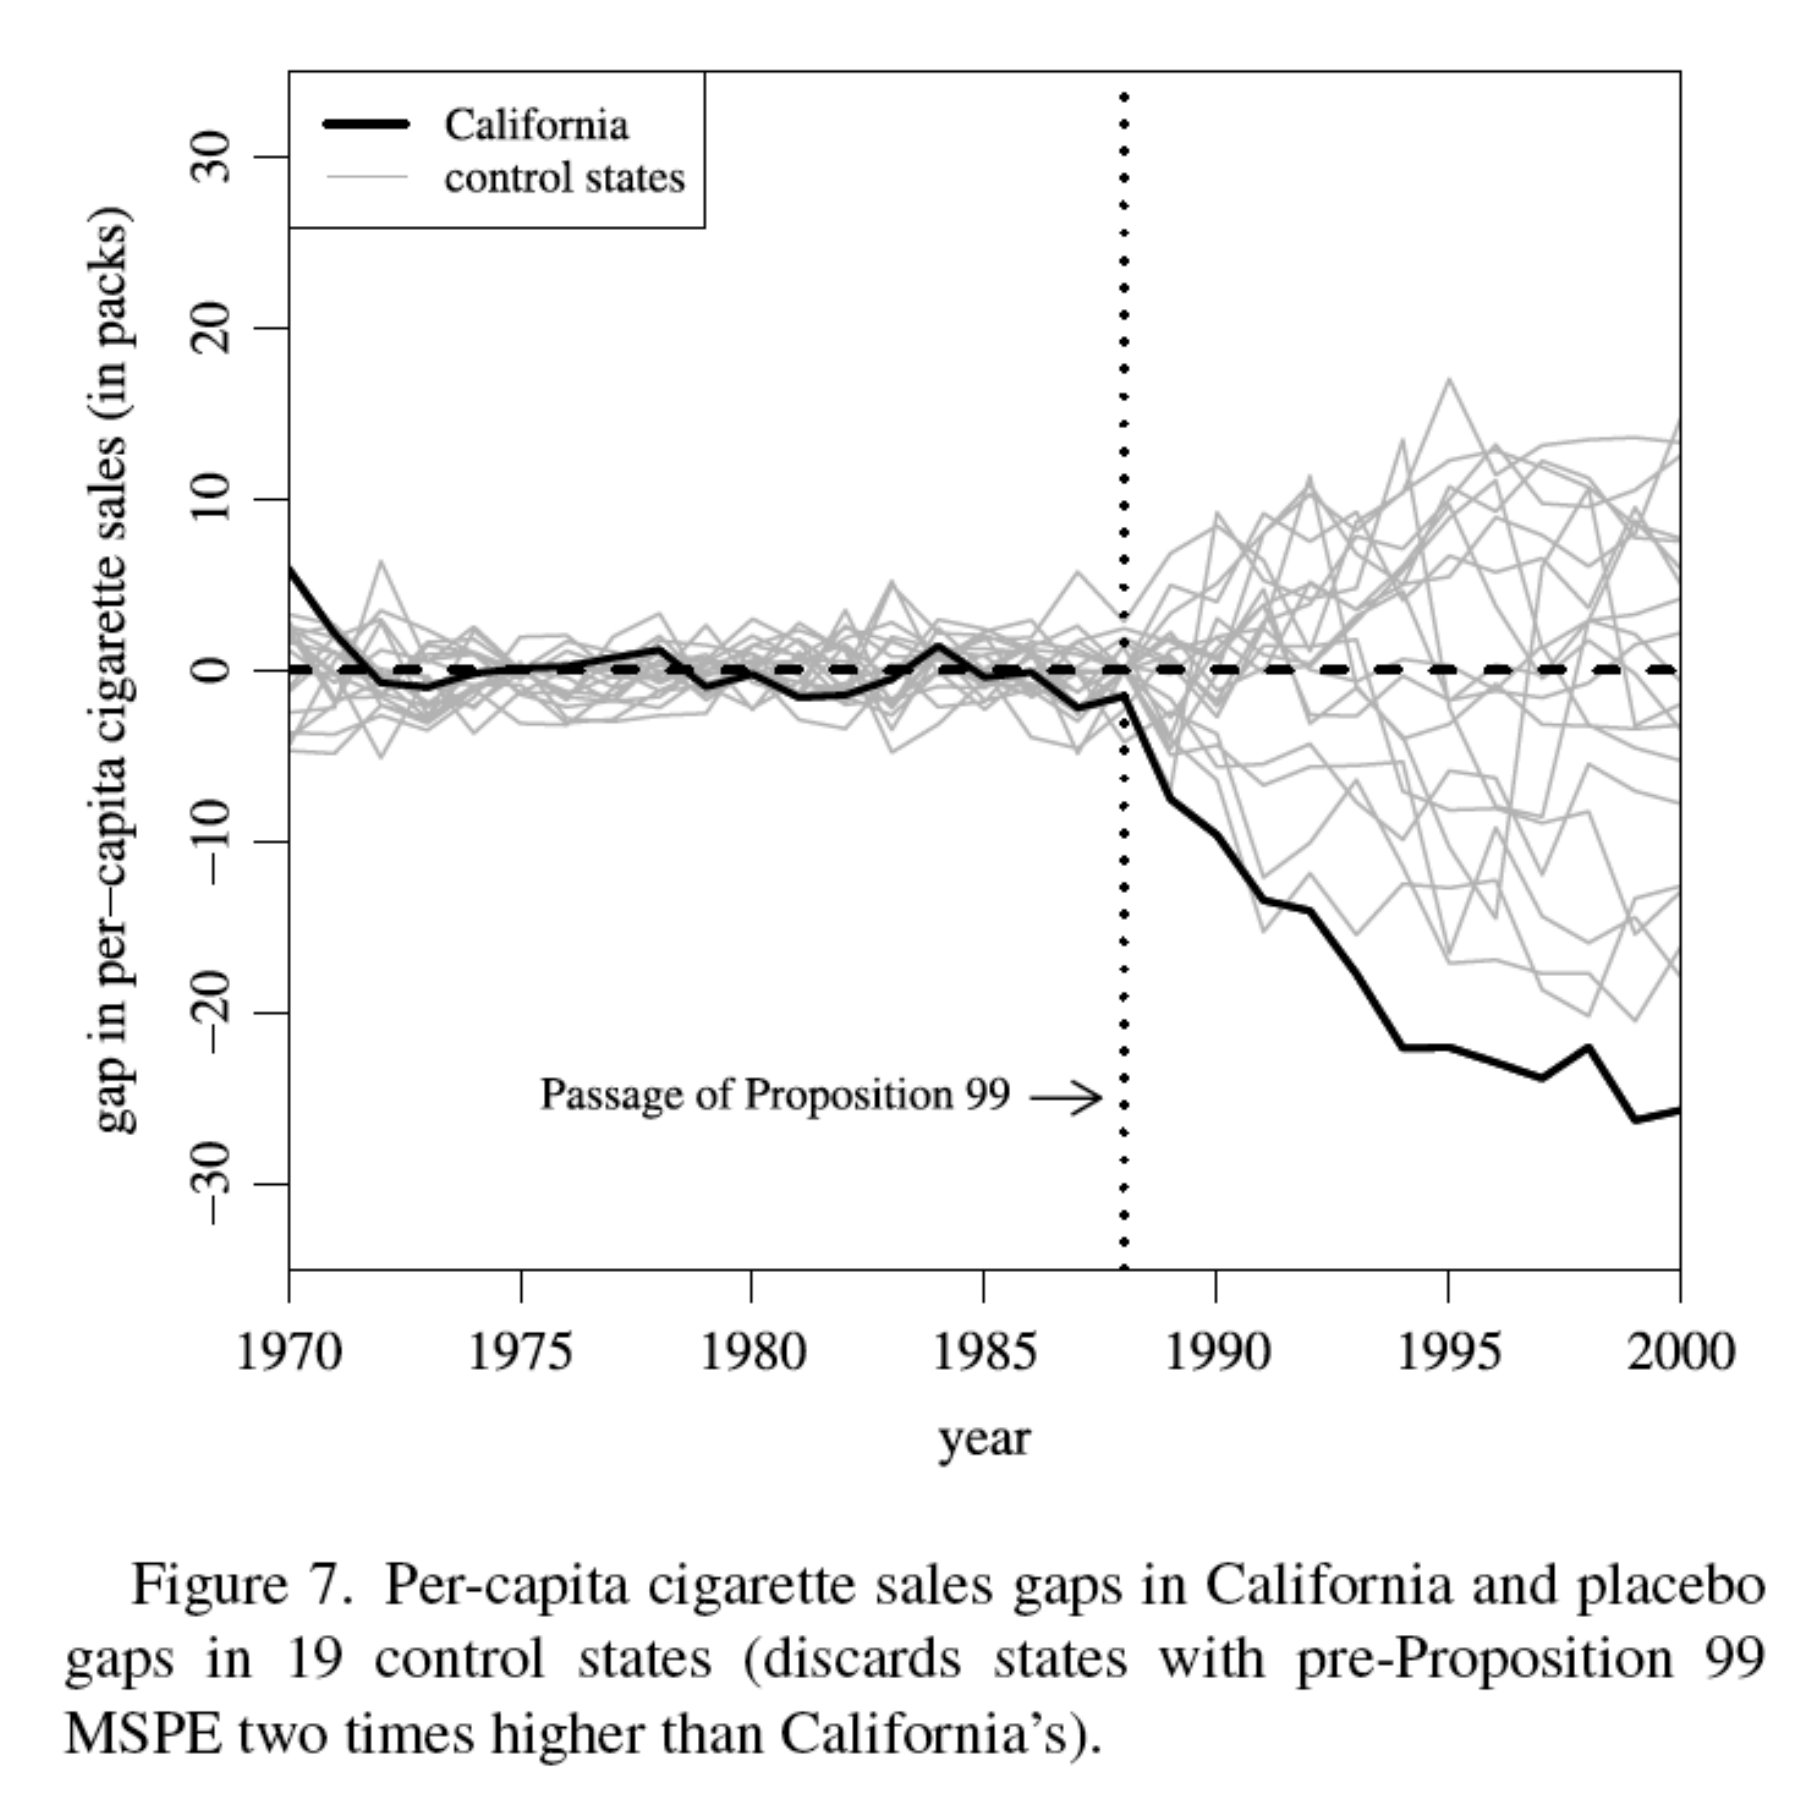
A large post-treatment gap is less informative if a placebo already had a large pre-treatment gap.
Abadie, Diamond, and Hainmueller compare results after excluding placebos with much worse pre-treatment fit.
Any exclusion rule should use pre-treatment information and be reported.
Sensitivity Checks
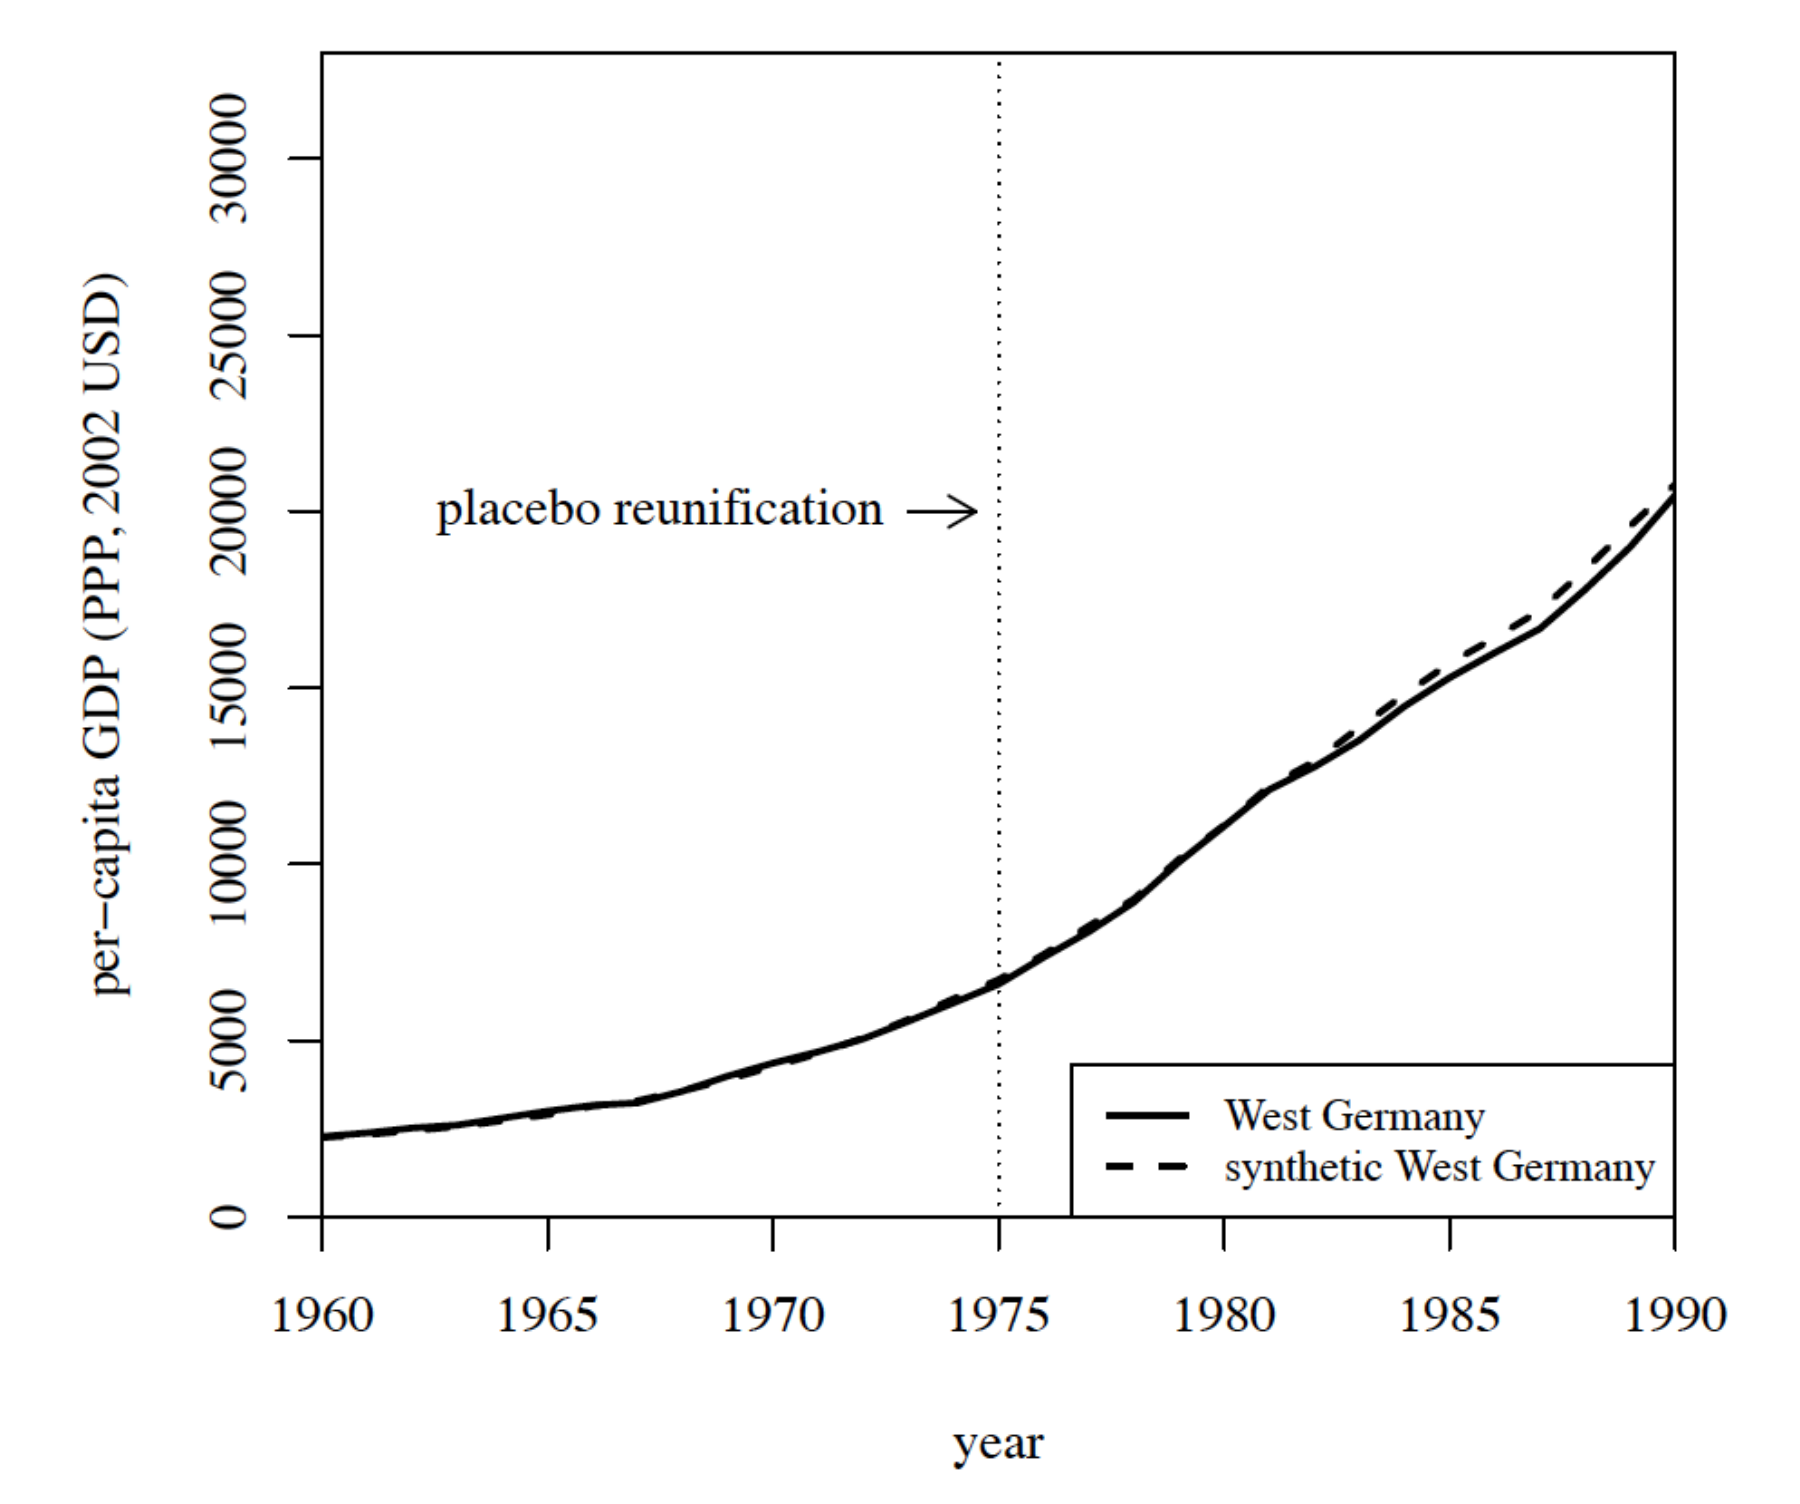
- Backdating: assign an earlier intervention date.
- Leave-one-out: refit after removing a donor with positive weight.
- Vary the donor pool.
- Vary predictors and pre-treatment windows.
- Examine alternative predictor weights.
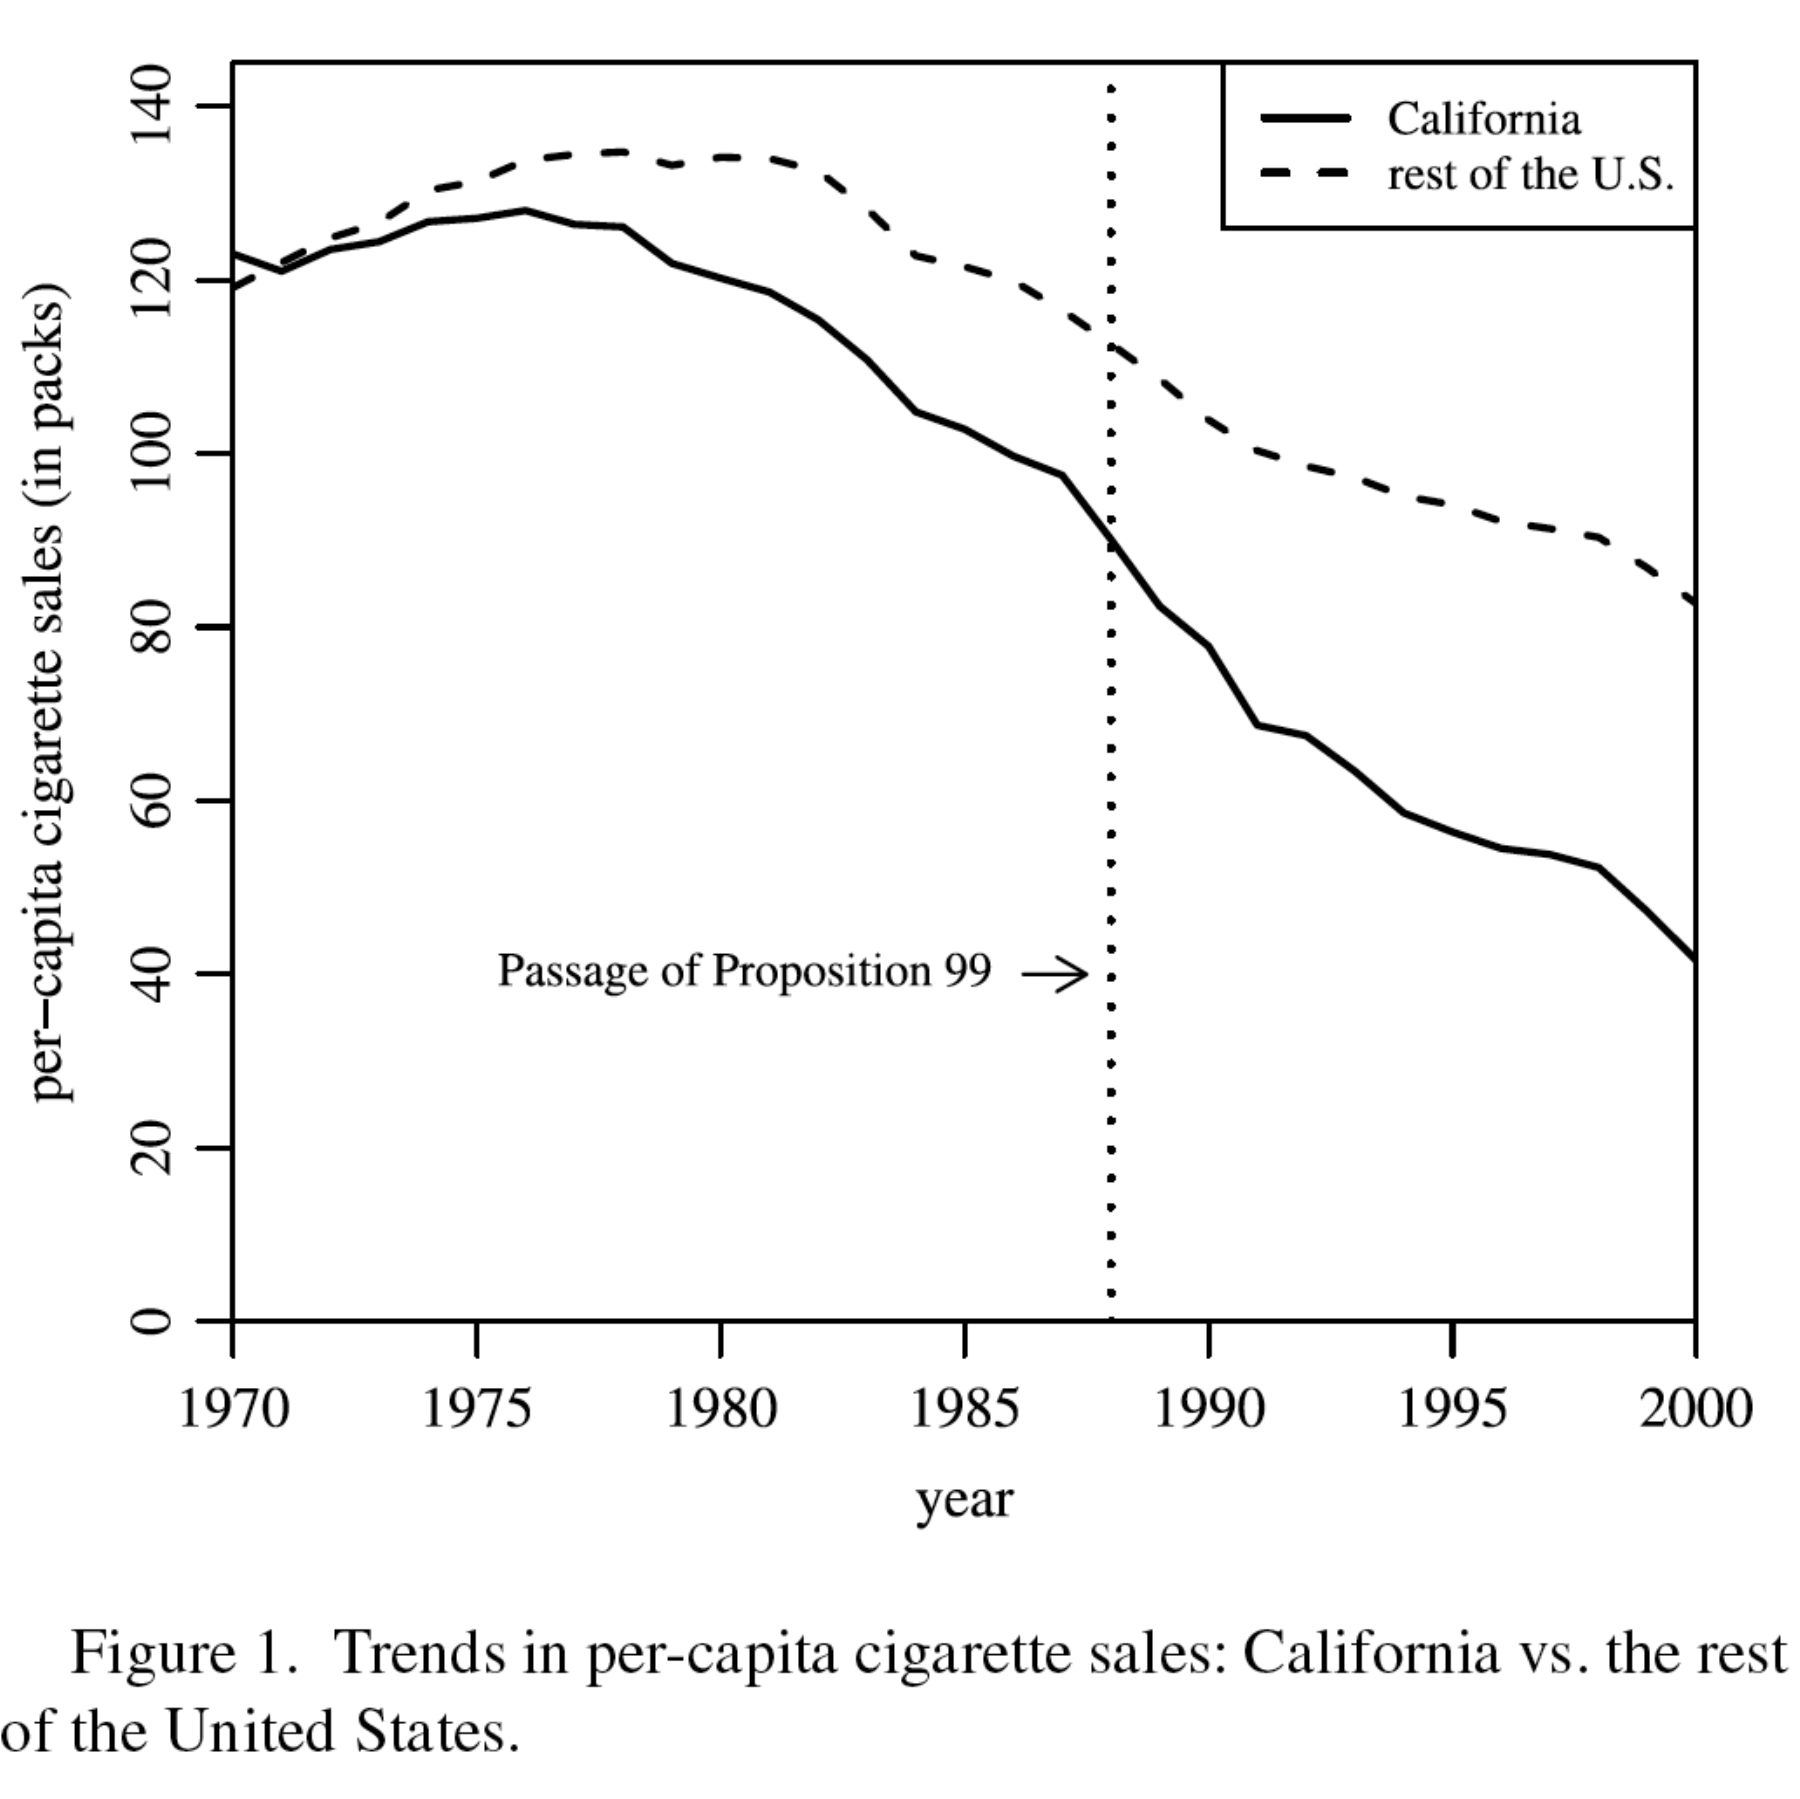
California: Policy and Data
For discussion: What did Proposition 99 change? What is the outcome, when does treatment begin, and which states can supply a comparison?
Explain what the estimated effect can tell us about the policy.
California: Table 1
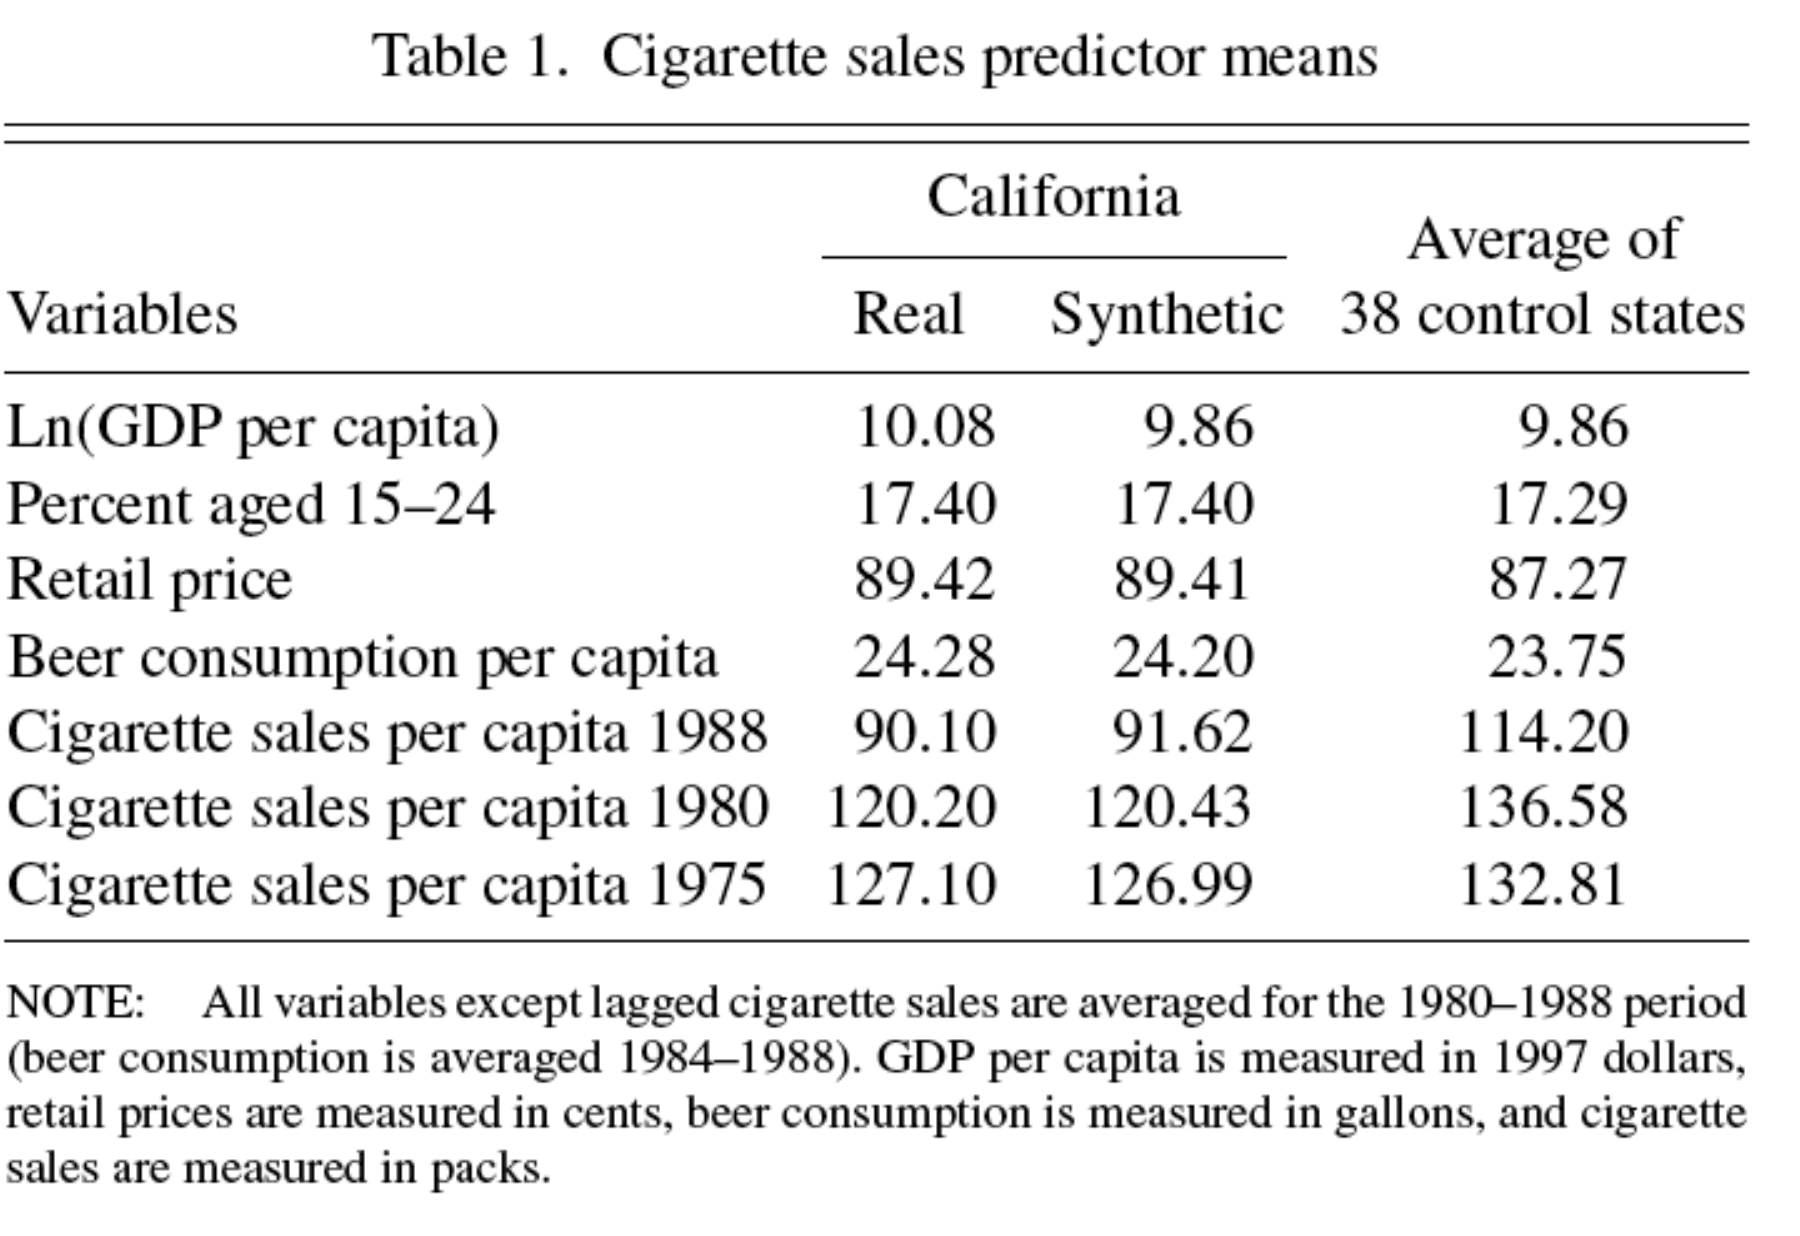
![]()
Abadie, Diamond, and Hainmueller (2010), Table 1.
For discussion: Compare California, synthetic California, and the donor-state average. Which predictors fit well, and where do differences remain?
California: Table 2
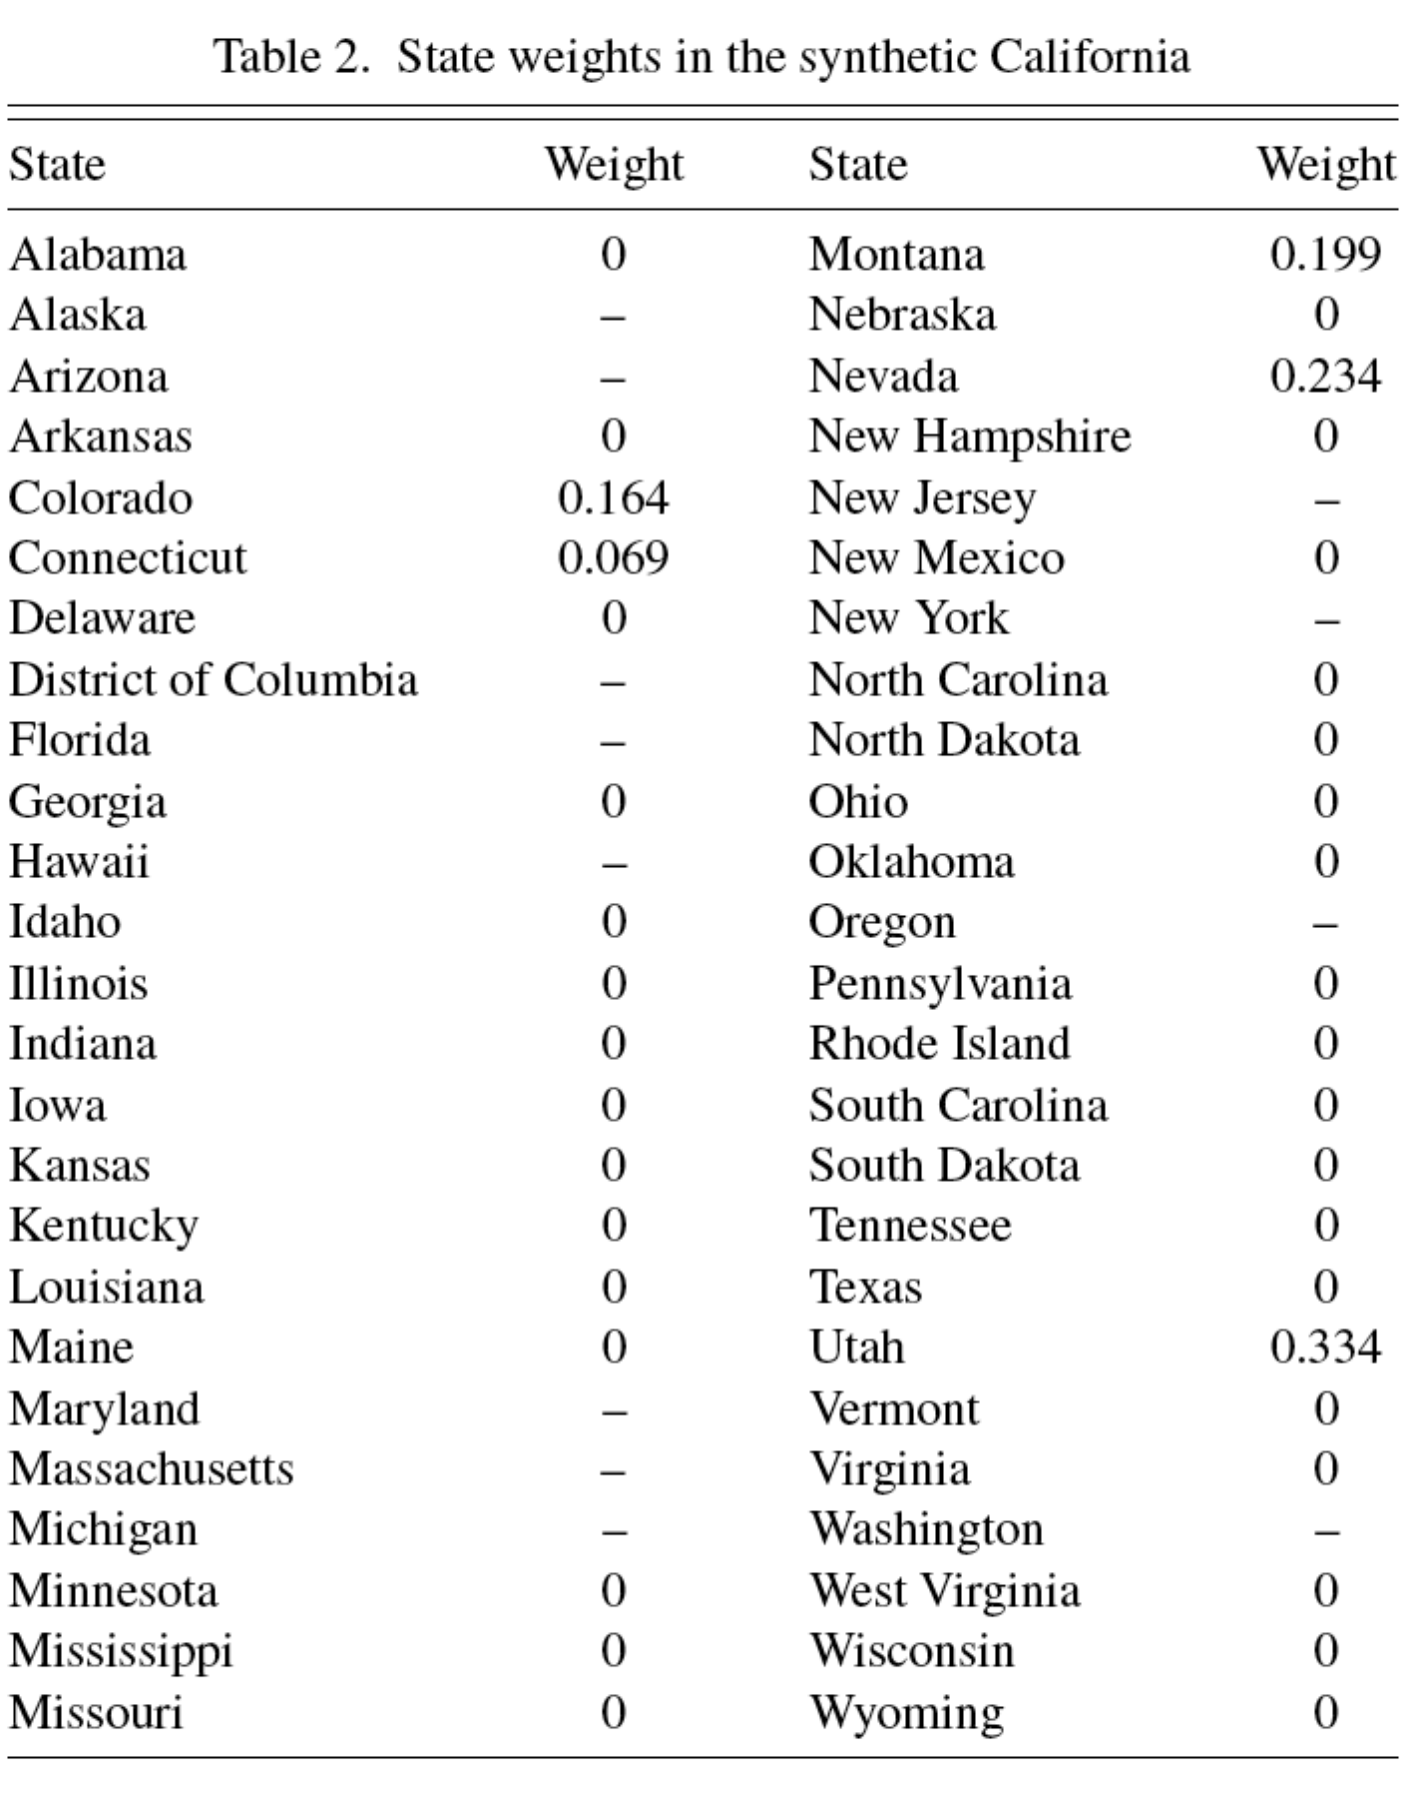
![]()
Abadie, Diamond, and Hainmueller (2010), Table 2.
For discussion: Which states contribute to synthetic California? Explain what a donor weight means and why many states receive zero weight.
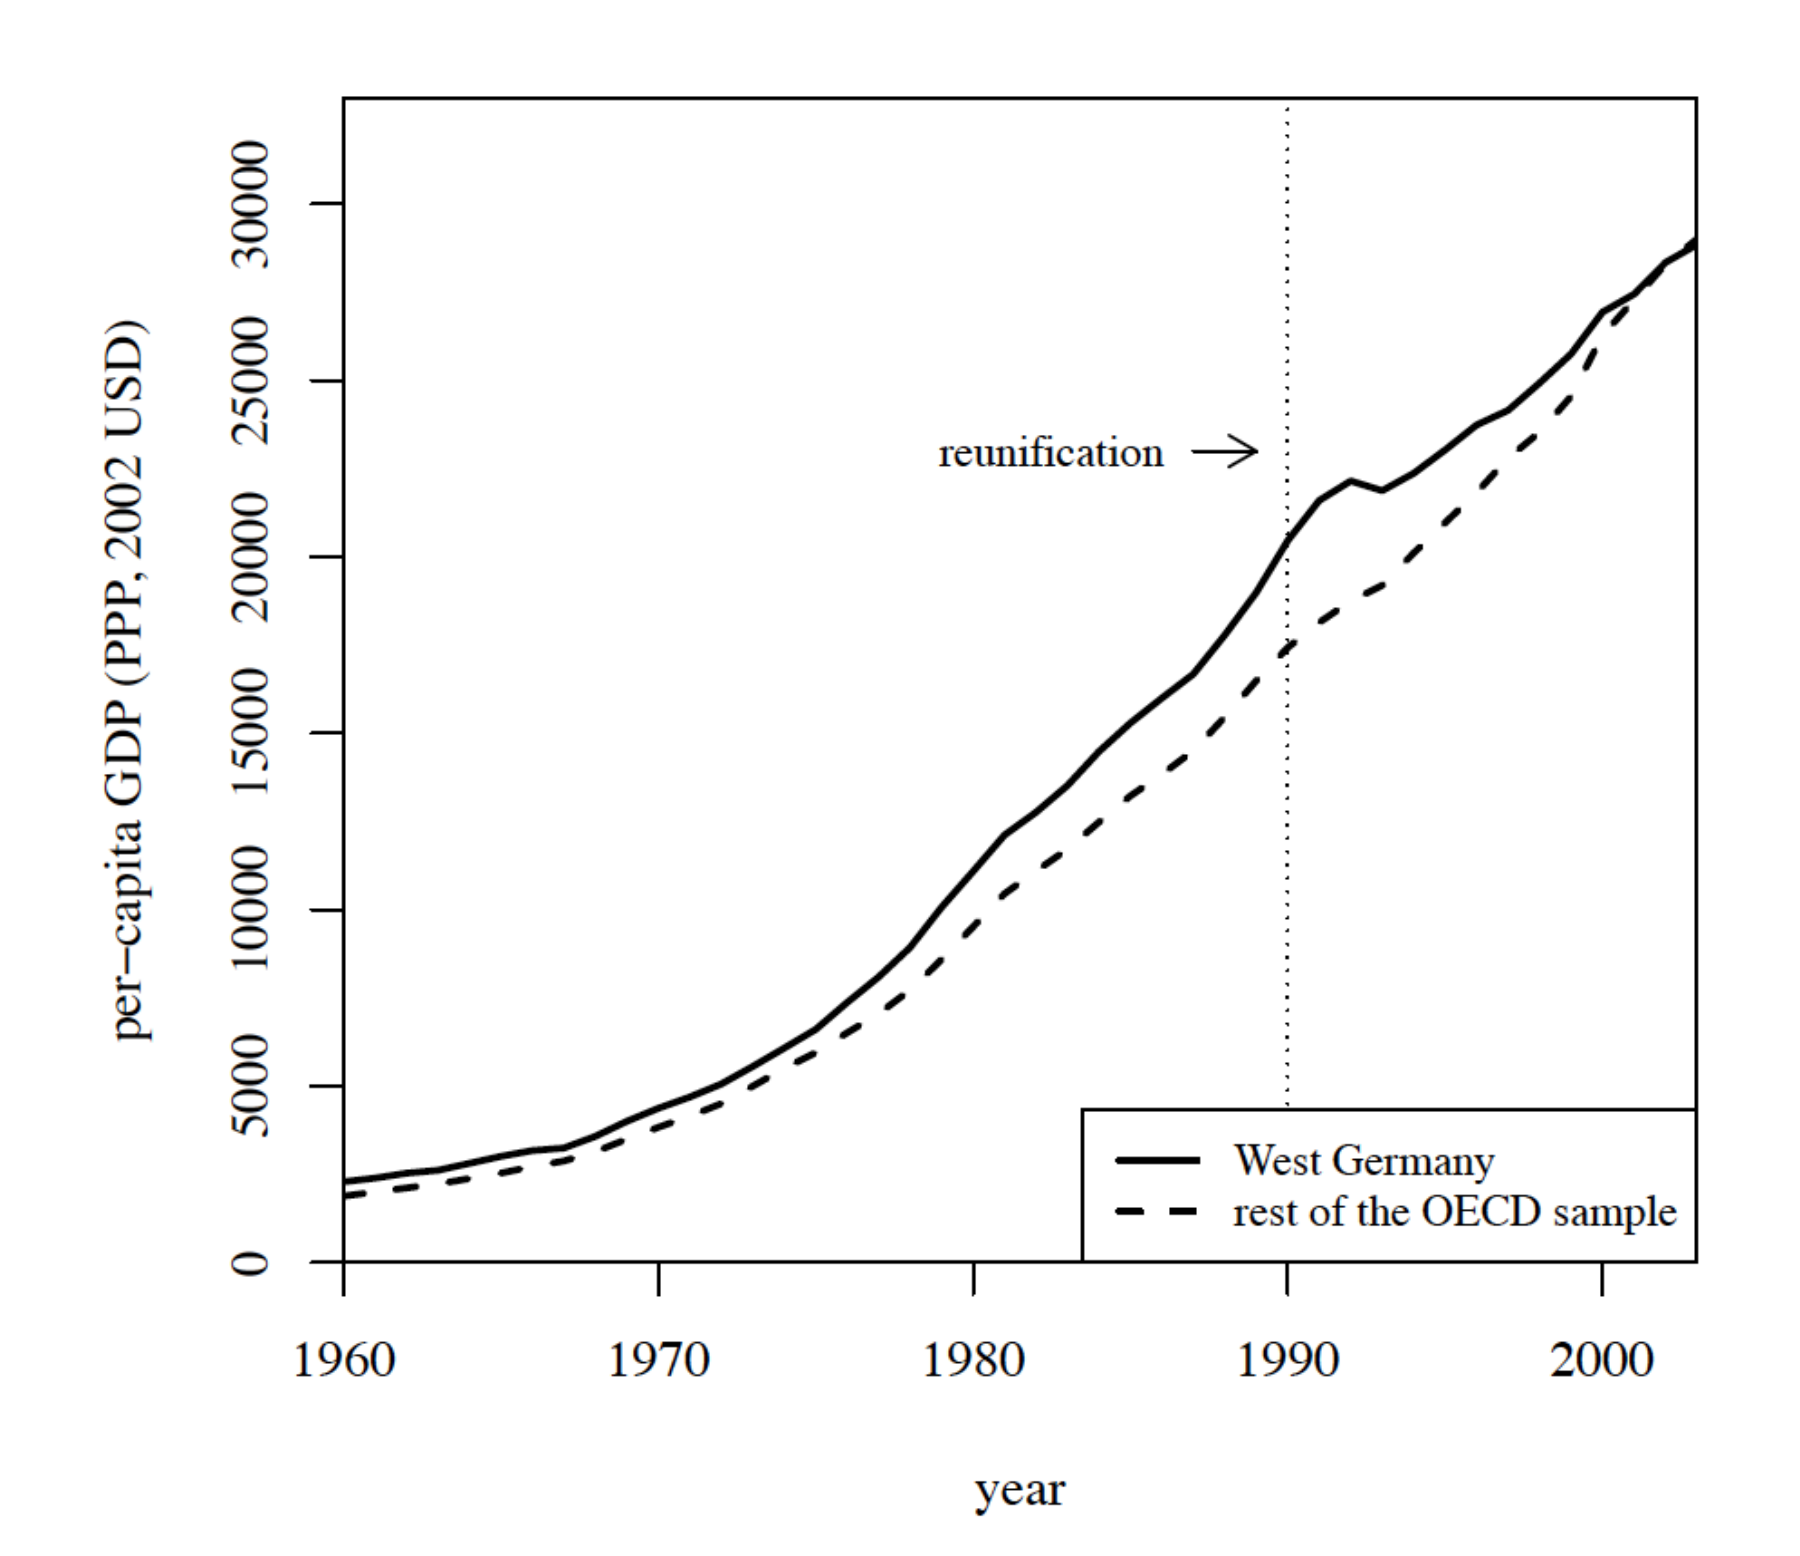
German Reunification: Policy and Data
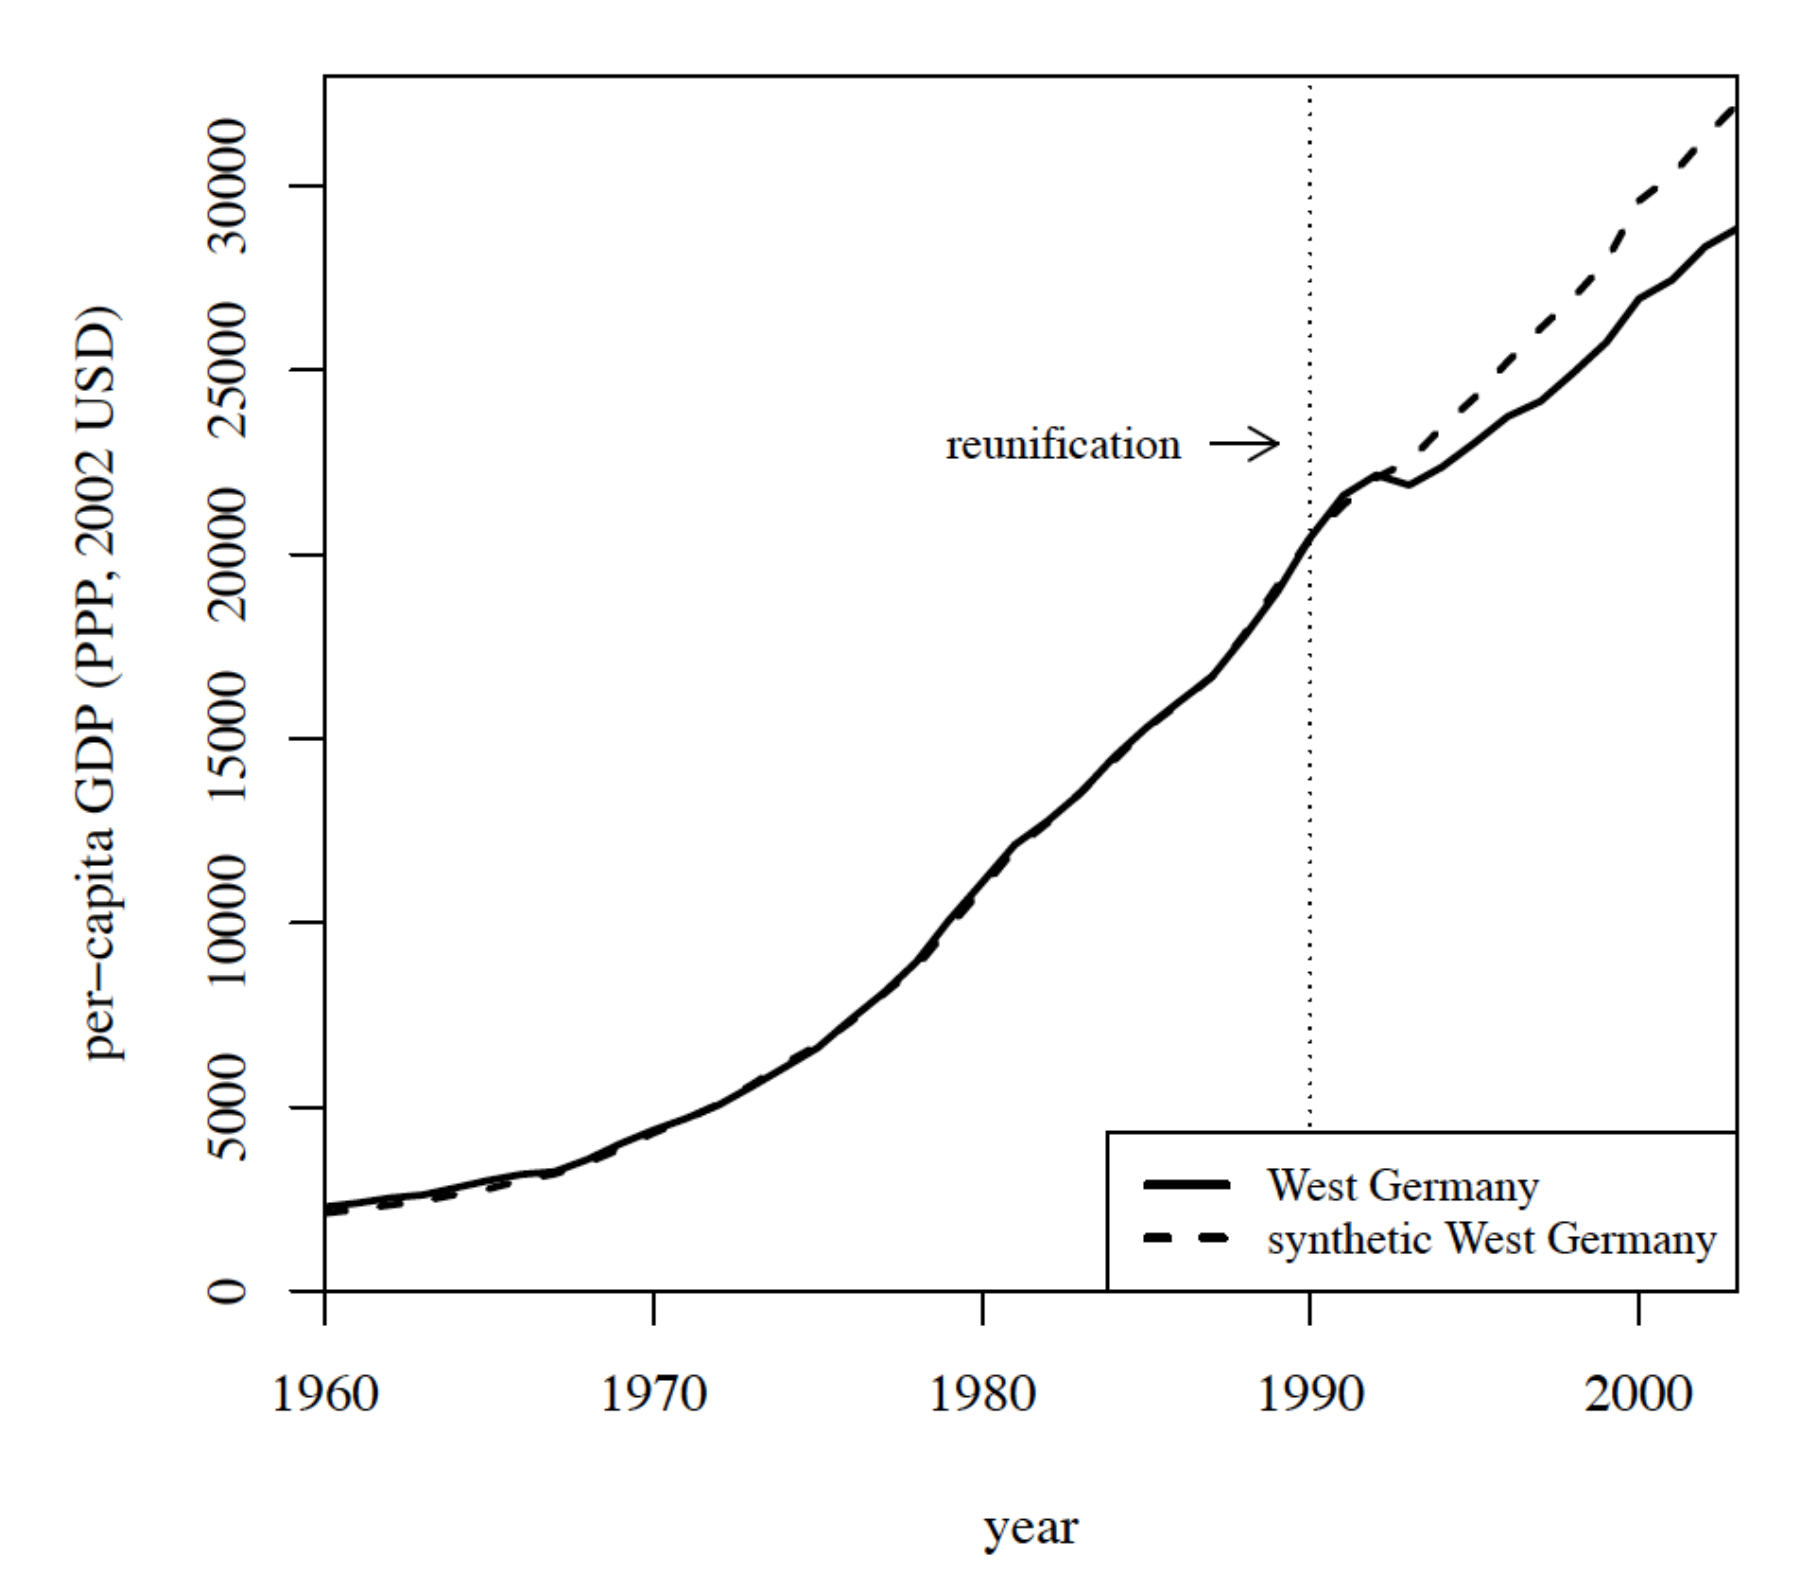
For discussion: What is the outcome and which Germany is being studied? What is the intervention date?
Explain the proposed counterfactual and the choice of donor countries.
Could reunification also affect the donor countries?
Reading the German Results: Erratum
The 2025 erratum corrects the GDP units to PPP current US dollars.
It also corrects the OECD sample averages in Table 2.
Use the corrected units when interpreting the figures and dollar gaps.
Where Do the Regression Weights Come From?
For each post-treatment year t, estimate across donor countries:
Y_{jt}=\beta_{0t}+\sum_{h=1}^{K}\beta_{ht}X_{hj}+u_{jt}.
Insert West Germany’s pre-treatment predictor values:
\widehat Y_{1t}^{0}=\widehat\beta_{0t}
+\sum_{h=1}^{K}\widehat\beta_{ht}X_{h1}.
This prediction can be written as \sum_{j=2}^{J+1}w_j^{\mathrm{OLS}}Y_{jt}.
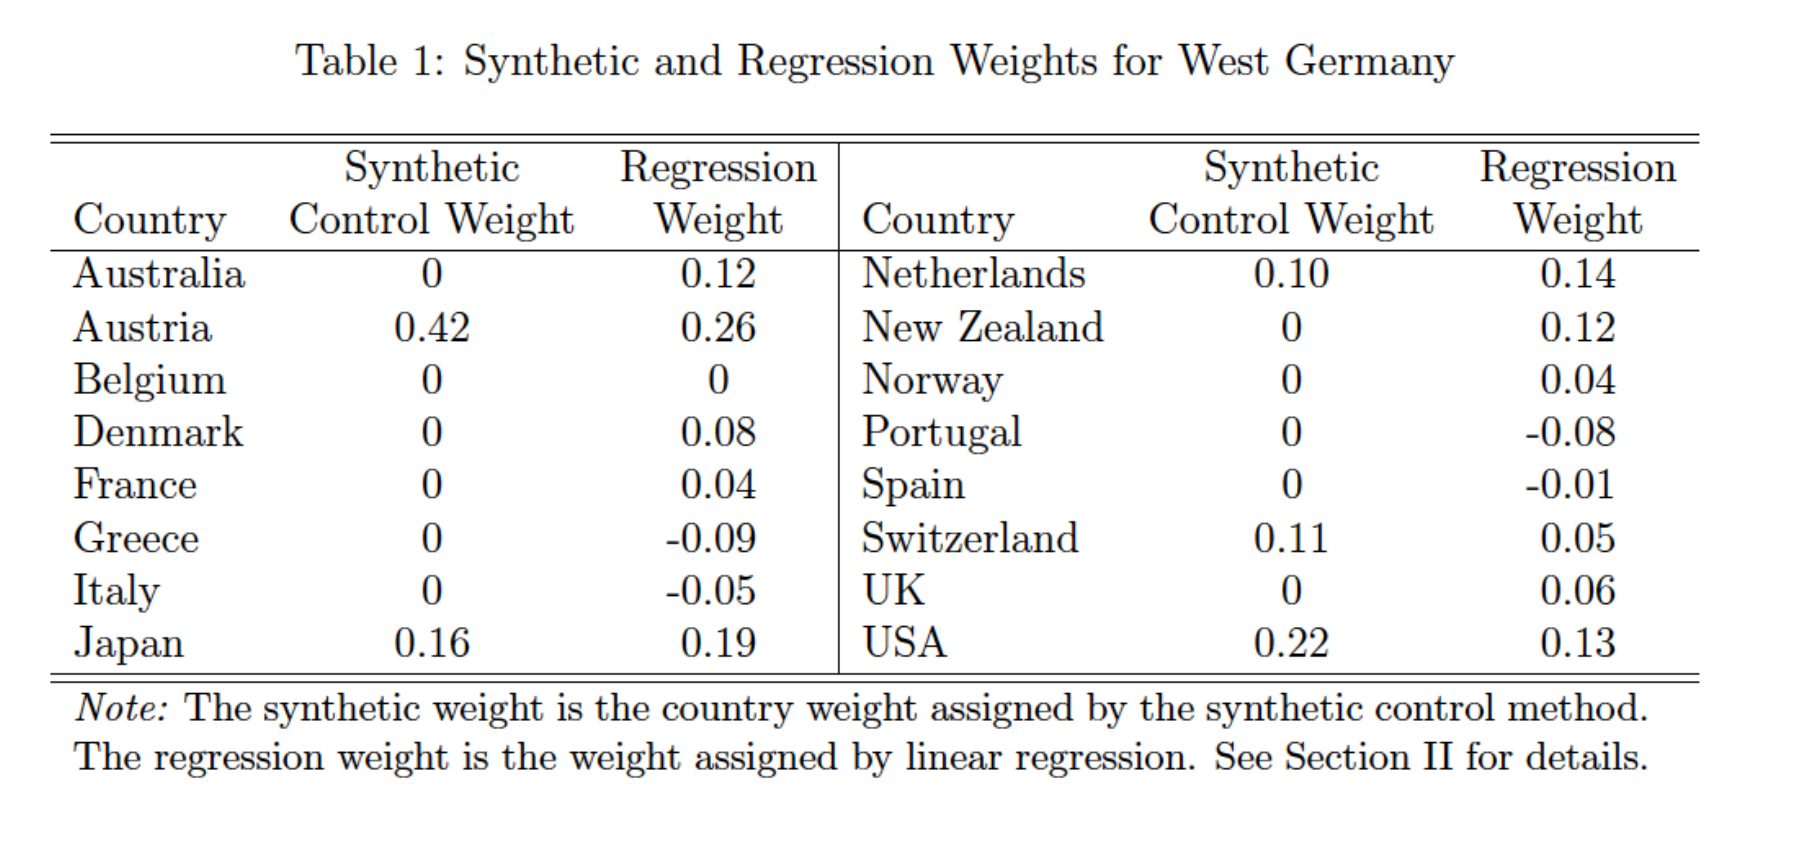
The table reports these implied country weights. They sum to one, but can be negative.
Germany: Table 1
![]()
Abadie, Diamond, and Hainmueller (2015), Table 1.
For discussion: Compare the synthetic-control and regression weights. What does each method permit, and which countries drive the synthetic comparison?
Germany: Corrected Table 2
| GDP per capita |
15808.9 |
15802.2 |
15037.8 |
| Trade openness |
56.8 |
56.9 |
35.3 |
| Inflation rate |
2.6 |
3.5 |
5.7 |
| Industry share |
34.5 |
34.4 |
34.2 |
| Schooling |
55.5 |
55.2 |
44.4 |
| Investment rate |
27.0 |
27.0 |
25.7 |
Abadie, Diamond, and Hainmueller (2025), erratum, Table 1 correcting the 2015 Table 2. GDP: PPP current US dollars.
For discussion: How does synthetic West Germany compare with the OECD average as a match for West Germany?
Assessing the Two Applications
- Is the donor pool substantively credible?
- Does the synthetic control fit the pre-treatment outcomes?
- Could anticipation, spillovers, or other shocks explain the gap?
- Is the gap unusual relative to credible placebos?
- Does the conclusion survive reasonable changes in the comparison?
Synthetic Control Requires Choices
Researchers choose the donor pool, predictors, pre-treatment window, validation period, and fitting procedure.
Report those choices and show the donor weights, fit, outcome paths, and sensitivity checks.
For policy, connect the estimated gap to the intervention and the population it represents.
References
- Abadie, A., A. Diamond, and J. Hainmueller (2010). “Synthetic Control Methods for Comparative Case Studies: Estimating the Effect of California’s Tobacco Control Program.” JASA 105(490): 493–505. Link.
- Abadie, A., A. Diamond, and J. Hainmueller (2015). “Comparative Politics and the Synthetic Control Method.” AJPS 59(2): 495–510. Link. See also the 2025 erratum.
- Abadie, A. (2021). “Using Synthetic Controls: Feasibility, Data Requirements, and Methodological Aspects.” JEL 59(2): 391–425. Link.
- Kaul, A., S. Klössner, G. Pfeifer, and M. Schieler (2022). “Standard Synthetic Control Methods: The Case of Using All Preintervention Outcomes Together With Covariates.” JBES 40(3): 1362–1376.